In this guide
Short answer
Use synthetic participants to generate hypotheses, rehearse an interview guide, identify obvious omissions, or explore desk-research questions. Do not use them to validate demand, estimate prevalence, create customer quotations, replace accessibility research, or represent lived experience. Label every generated artifact and require real evidence before a decision advances.
Why the boundary matters
Models tend to produce plausible, cooperative, averaged answers shaped by training data and prompts. They do not encounter the product, bear the switching cost, experience the environment, or reveal unexpected behavior. More personas create more generated variation—not a sampled population.
A safe protocol
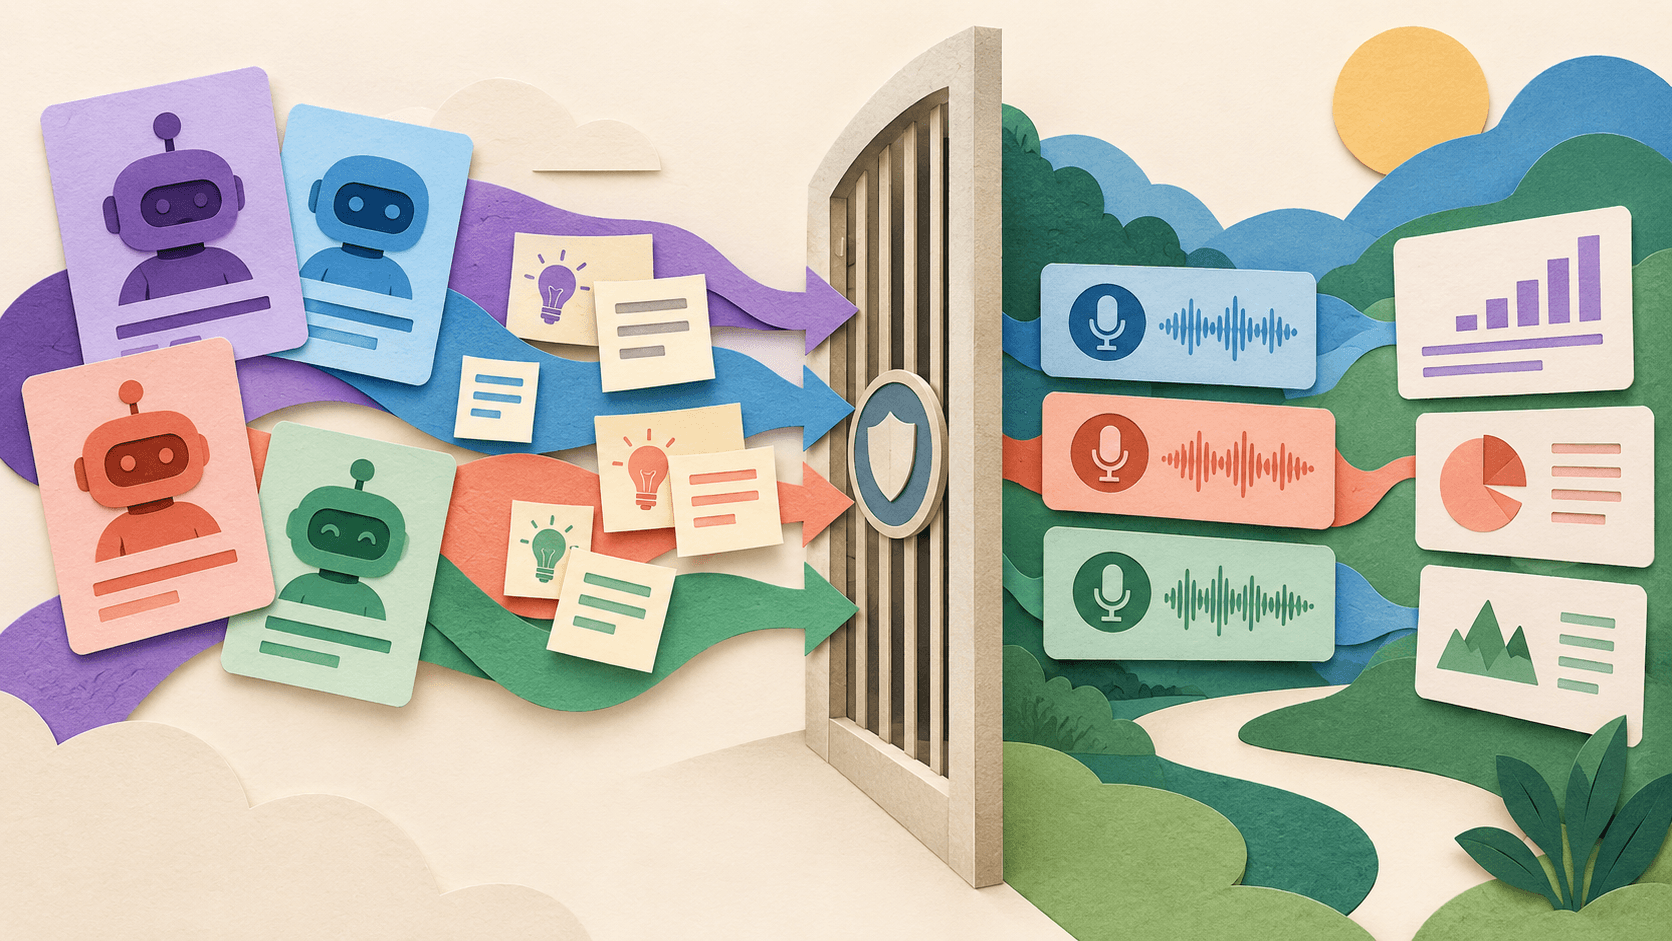
Write the hypothesis first, label the simulation, separate its storage from participant data, document model and prompt, generate disconfirming cases, and convert every output into a question for real research. Stop if stakeholders cite the simulation as customer evidence or use it to cancel participant recruitment.
Transparency
How this guide was checked
About this article
How this article was prepared
- Evaluation type
- Source-based research
- Last reviewed
- Evidence
- 4 listed sources
We label hands-on testing separately. Research-based articles draw on product documentation and other cited sources, rather than direct use of every plan. Read the full methodology.
Editorial basis
Sources and testing
- Editorial basis
- Source-based research
- Primary references
- 4
- Products covered
- 3
- Last checked
- 2026-10-03
Important limits
- • Research on synthetic participants is evolving and performance varies by task and context.
- • This guide does not validate any commercial synthetic-participant product.
Sources and references
References cited by this article. Check the original source for scope, dates and current terms.
Frequently asked questions
Can AI replace human judgment in synthetic-participant research?
No. AI can accelerate retrieval, organization, and first-pass analysis, but an accountable person must verify evidence, context, permissions, and the final decision.
What should a team measure?
Measure source accuracy, correction time, missed counterevidence, permission behavior, export quality, and cost per accepted deliverable—not output volume.
What data is safe to use?
Only data covered by the participant notice, contract, organizational policy, and vendor terms. Remove unnecessary identifiers and keep the original evidence outside the model workflow.
What is the minimum audit trail?
Keep the source manifest, prompt and model record, output, reviewer corrections, approval decision, and deletion or retention record.
Tools mentioned in this article
ChatGPT
The general-purpose AI assistant that started it all
OpenAI's flagship conversational AI model, powering everything from casual chat to complex reasoning, coding, and creative work.
Claude
Anthropic's thoughtful, safety-focused AI with exceptional long-form reasoning
Claude excels at deep analysis, long-form writing, and nuanced reasoning. Built by Anthropic with a focus on safety and helpfulness.
Read next