In this guide
Short answer
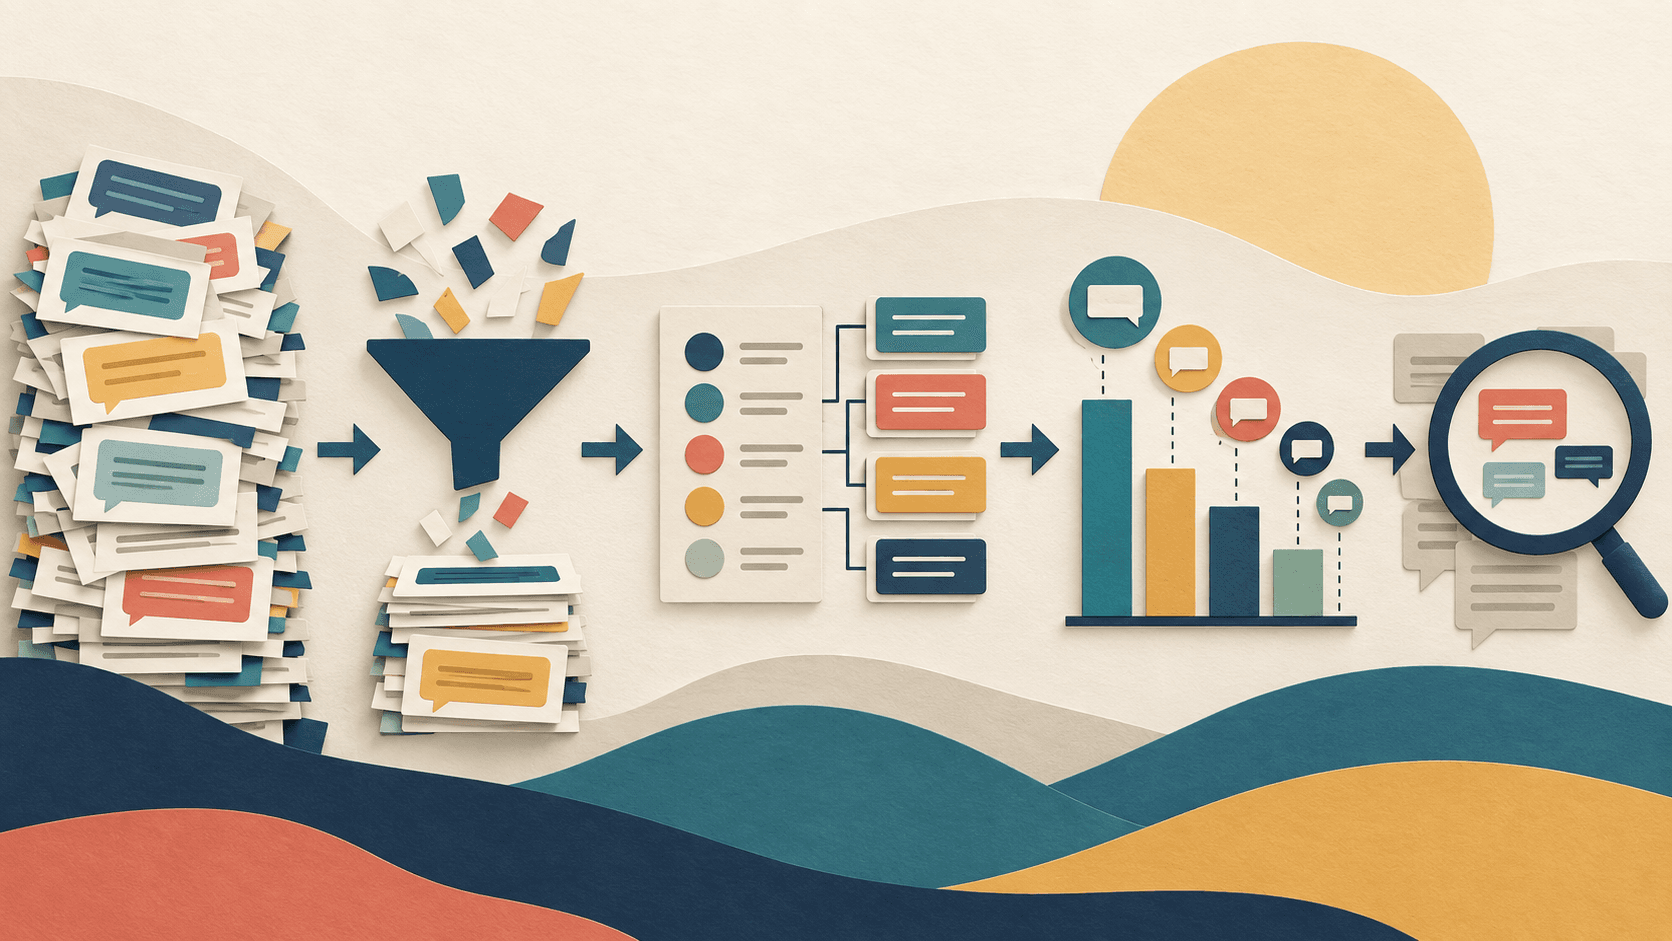
Analyze open-ended survey responses with AI by separating preparation, qualitative coding, validation, and quantification. Clean the export without rewriting respondents, draw a diverse calibration sample, build and test a codebook, classify with source references, manually audit errors and minority views, and only then calculate counts against the correct denominator.
Free workflow pilot checklist
Test the workflow before you buy the tool.
Use our buyer checklist to plan a task, assign a reviewer and track time saved. You’ll also receive the weekly AI briefing.
Prepare the data
Preserve a read-only export. Create a working copy with stable response IDs, the question wording, relevant segmentation fields, language, survey branch, date, and missingness. Remove direct identifiers that are unnecessary for analysis. Do not merge “blank,” “not asked,” “prefer not to answer,” and unusable text into one category.
Inspect before automating
Read a varied sample across time, customer segment, response length, sentiment, language, and survey path. Note spelling, sarcasm, multiple ideas in one answer, copied text, sensitive disclosures, and responses that address a different question. This sample becomes the calibration set.
Create a question-specific codebook
Codes should answer the research question, allow multiple labels when one response contains several ideas, and include an “other/unclear” route. Define inclusion and exclusion rules. Avoid importing a taxonomy from another question simply because it already exists.
Validate classification
Compare AI labels with reviewed human labels on a held-out sample. Inspect accuracy per code, not just overall agreement: a dominant category can hide failure on rare but consequential feedback. Review quoted evidence and re-run after material codebook changes.
Count honestly
Specify whether percentages use all respondents, people shown the question, people who answered it, or coded comments as the denominator. Distinguish respondents from mentions when multi-label coding is allowed. Do not claim population prevalence from a biased response sample.
Protect the minority signal
Review rare codes, high-severity complaints, accessibility barriers, safety concerns, churn reasons, and segment-specific patterns even when they do not rank by volume. AI clustering tends to make the center of a dataset look cleaner than its edges.
Publish a traceable report
For each finding, show the question, response base, coding method, dates, segment, count convention, representative quotations, counterexamples, validation sample, limitations, and owner. Readers should know what was measured and be able to inspect de-identified source responses under appropriate access.
Transparency
How this guide was checked
About this article
How this article was prepared
- Evaluation type
- Source-based research
- Last reviewed
- Evidence
- 4 listed sources
We label hands-on testing separately. Research-based articles draw on product documentation and other cited sources, rather than direct use of every plan. Read the full methodology.
Editorial basis
Sources and testing
- Editorial basis
- Source-based research
- Primary references
- 4
- Products covered
- 3
- Last checked
- 2026-10-02
Important limits
- • This guide does not make a convenience survey statistically representative.
- • Validation thresholds should reflect the consequence of each decision and the quality of the response data.
Sources and references
References cited by this article. Check the original source for scope, dates and current terms.
Frequently asked questions
Can AI analyze thousands of survey comments?
Yes, but scale does not remove the need for cleaning, a question-specific codebook, a held-out validation sample, rare-code review, and correct denominators.
Can I report theme percentages?
Yes if you define the denominator and multi-label rule clearly, validate classification, and avoid implying population prevalence when the respondents are not representative.
Should sentiment analysis replace coding?
No. Sentiment is a coarse signal and often misses mixed views, sarcasm, severity, reasons, proposed fixes, and the specific subject of a comment.
How should rare responses be handled?
Review them separately. Low frequency can still matter when a response describes harm, accessibility failure, security risk, churn, or a problem concentrated in one segment.
Tools mentioned in this article
ChatGPT
The general-purpose AI assistant that started it all
OpenAI's flagship conversational AI model, powering everything from casual chat to complex reasoning, coding, and creative work.
Claude
Anthropic's thoughtful, safety-focused AI with exceptional long-form reasoning
Claude excels at deep analysis, long-form writing, and nuanced reasoning. Built by Anthropic with a focus on safety and helpfulness.
Google Gemini
Google's deeply integrated AI assistant with unmatched access to Google's ecosystem
Gemini combines powerful AI with Google's vast data ecosystem — Search, Gmail, Docs, YouTube, and more — for a uniquely integrated experience.
Read next
Recommended for you
AI Adoption for Small Business: A Readiness Guide for 2026
Adoption begins with a business constraint and an operating model—not a company-wide license purchase or an order to ‘use AI more.’
A readiness assessment for owners deciding whether, where, and how their business should adopt AI responsibly.
Read guide
AI Tools for Nonprofits in 2026: Build a Practical Mission-First Stack
Best AI Writing Tools in 2026: 9 Picks by Use Case, Budget, and Workflow
TypingMind Review 2026: Multi-Model Chat, Pricing, and Privacy