Gauntlet Loop Guide: How the Builder-Critic Method Works
The method can push an agent past its first acceptable draft, but only when the reference is inspectable, the critic is independent, and a human controls the budget.
Bottom line
A practical, evidence-bounded guide to Gauntlet Loop: its reference-bar method, builder-critic cycle, setup, costs, failure modes, and safe stopping rules.
Editorial accountability
Who checked this guide
- Evaluation type
- Research-based verification
- Last materially checked
- Evidence
- 4 listed sources
Hands-on testing is identified explicitly. Research-based coverage uses cited product documentation and other named sources; it does not imply every paid plan was used. Read the full methodology.
Editorial basis
What this guidance is based on
- Editorial basis
- Source-led analysis
- Primary references
- 4
- Products covered
- 2
- Last checked
- 2026-09-17
Important limits
- • Features, availability, and pricing can change after publication; confirm consequential details with the provider.
In this guide
*This research-based guide explains Matt Shumer's publicly documented method and open-source Claude of Duty artifact. DiscoverAI did not reproduce the many-hour game run, and public demonstrations do not establish a general success rate.*
The short answer
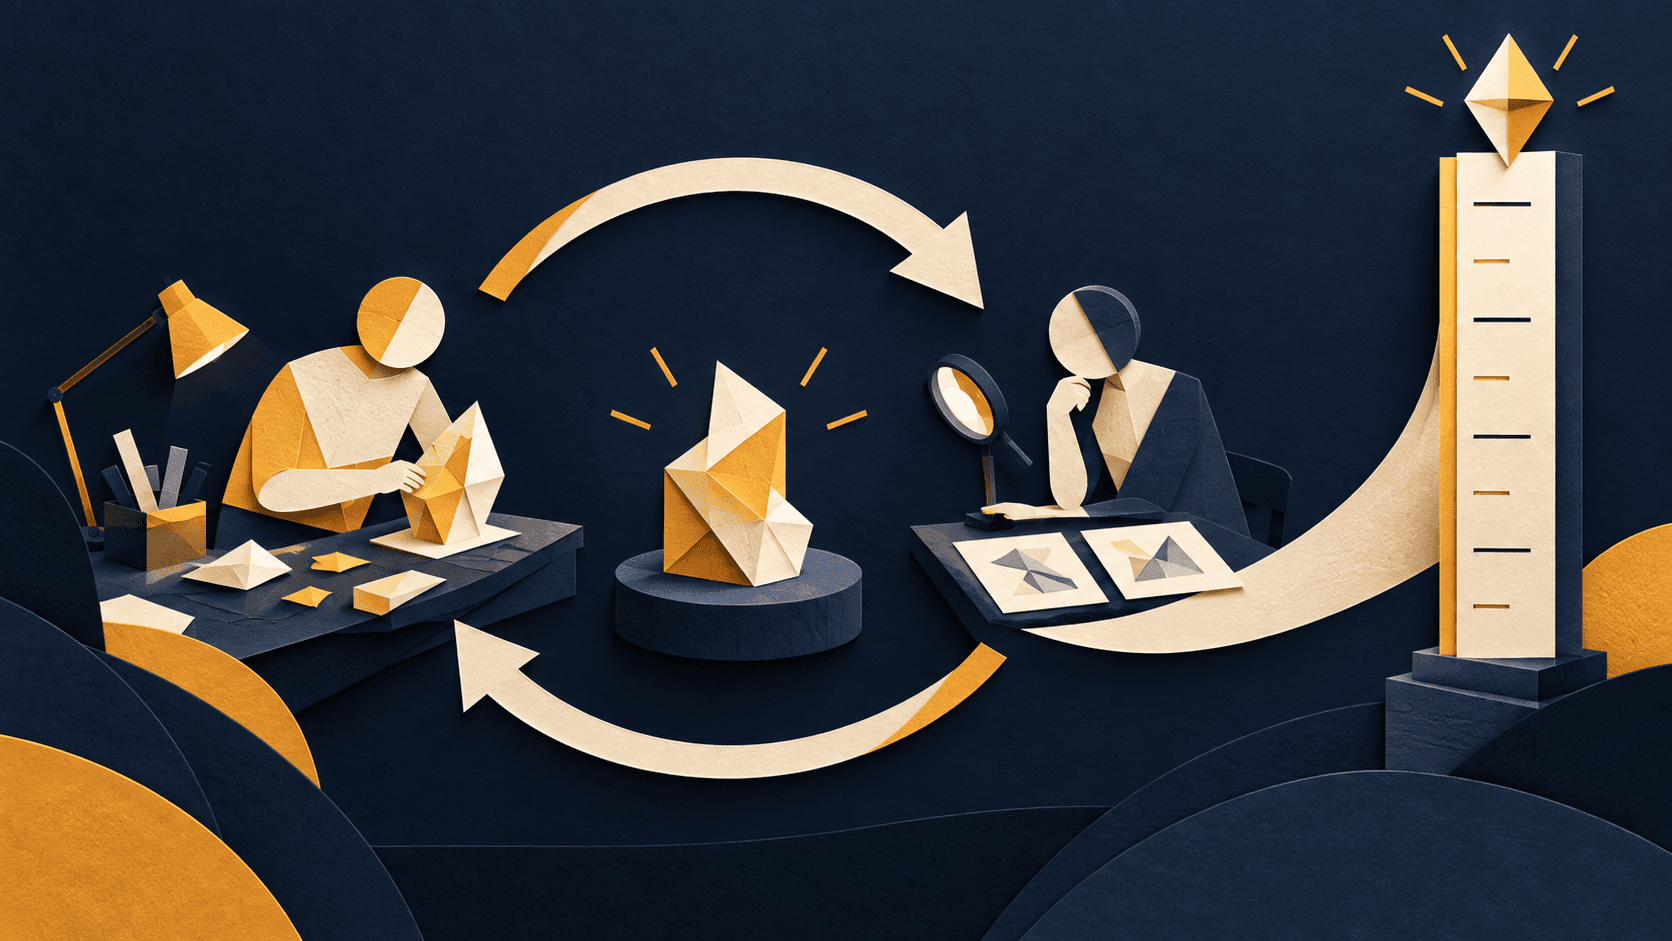
Gauntlet Loop is an agent-workflow pattern that makes a builder improve an artifact until a separate critic prefers it to a concrete, inspectable reference—or a human stops the run. A lead agent breaks the goal into judgeable parts, fresh-context builders work on them, and independent critics compare the real output with the chosen bar.
The technique is best suited to ambitious work whose quality can be inspected repeatedly: interfaces, games, writing, research artifacts, or code with strong tests and measurable performance. It is a poor fit for routine changes, vague creative briefs, or work where no reliable evaluator exists.
Where did Gauntlet Loop come from?
Matt Shumer named the method after using a short prompt to direct Claude Code to build the open-source Claude of Duty game. The prompt asked the agent to split the work among subagents, use separate harsh visual critics, compare the result with real Call of Duty references, and continue when its version lost.
The public repository makes the prompt and resulting code inspectable, but it does not turn one striking demo into a benchmark. The defensible conclusion is narrower: a strong reference, task decomposition, independent evaluation, and repeated revision can organize a long agent run more rigorously than a single generate-and-accept step.
How does the loop work?
- State the outcome. Describe what should exist without prescribing every implementation choice.
- Choose a real bar. Use a named page, repository, sample, test suite, latency target, or other artifact the critic can actually inspect.
- Split the work. Break the goal into units that can be built and judged independently.
- Separate builder from critic. Give the critic the goal, rules, reference, and finished artifact—but not the builder's rationale.
- Make the verdict concrete. Prefer a blind side-by-side choice or an executable threshold over a drifting score.
- Revise the largest gap. Send specific evidence back to the builder, then evaluate the actual new artifact.
- Stop deliberately. End when the acceptance bar is met, the budget expires, progress stalls, or a human decides the remaining gap is not worth the cost.
For software, visual preference alone is insufficient. Pair the reference comparison with tests, accessibility checks, security review, performance limits, and a final human diff review.
Why can it improve agent output?
The loop changes the incentive from “produce something plausible” to “survive a comparison.” Fresh critics are less exposed to the builder's explanations and sunk-cost reasoning. Small comparison units also make feedback actionable: “this navigation loses to the reference at mobile width” is more useful than “make the site better.”
This resembles the evaluator-optimizer pattern described in Anthropic's agent guidance: one model produces a response while another evaluates and supplies feedback over multiple turns. The advantage depends on evaluation quality. If the critic cannot open the reference, run the code, inspect the pixels, or verify claims, the apparent rigor is theater.
What can go wrong?
The most common failure is a vague or unreachable bar. A critic may invent what it cannot inspect, approve superficial similarity, or optimize the artifact toward a reference that does not match the user's real goal. Builders and critics can also share model biases, reward cosmetic changes, or loop without meaningful progress.
Long multi-agent runs consume substantial tokens and compute. They also widen the permission surface: more agents may read files, execute tools, access networks, or change code. Use a clean branch, least-privilege credentials, explicit prohibited actions, spend and time ceilings, checkpointed artifacts, and human approval before commits, deployment, purchases, messages, or data deletion.
A safer starter template
Define one outcome, one fetchable reference, and three to five acceptance checks. Cap the first experiment by time and spend, even if the aspirational method is open-ended. Require the orchestrator to report each comparison, evidence used, changes made, and remaining failures. If two rounds produce no measurable improvement, stop and reconsider the bar or decomposition.
The verdict
Gauntlet Loop is a useful method for quality-sensitive work when “better” can be grounded in an artifact or measurement. Its durable idea is not unlimited autonomous labor; it is that the maker should not be the only judge. Use it selectively, bound the real-world risk, and treat the public demo as inspiration rather than proof of predictable results.
Sources and verification
Product details and claims were checked against the following primary sources.
Frequently asked questions
What is the Gauntlet Loop?
It is an agent workflow in which builders repeatedly improve an artifact while separate fresh-context critics compare the real output with a concrete reference or measurable quality bar.
Does Gauntlet Loop require Claude Code?
No. The pattern can run in any agentic environment that can inspect artifacts and isolate builders from critics, although the original public example used Claude Code and its subagent capabilities.
When should you avoid a Gauntlet Loop?
Avoid it for routine work, vague goals, low-stakes tasks, or situations without an inspectable reference or reliable evaluator. A normal implementation and review is cheaper and clearer.
How should a Gauntlet Loop stop?
Stop when explicit acceptance checks pass, the human-approved spend or time budget is reached, progress stalls, or the remaining gap is not worth the additional cost and risk.
Found this useful?
Get the next one in your inbox.
One five-minute briefing a week: a meaningful change, a practical workflow, and a clearer tool decision—already filtered for lean teams.
Free · one email a week · unsubscribe any time
Tools mentioned in this article
Claude
Anthropic's thoughtful, safety-focused AI with exceptional long-form reasoning
Claude excels at deep analysis, long-form writing, and nuanced reasoning. Built by Anthropic with a focus on safety and helpfulness.
ChatGPT
The general-purpose AI assistant that started it all
OpenAI's flagship conversational AI model, powering everything from casual chat to complex reasoning, coding, and creative work.
Read next
Recommended for you
Gauntlet Loop vs Claudex Loop: Which Workflow Fits?
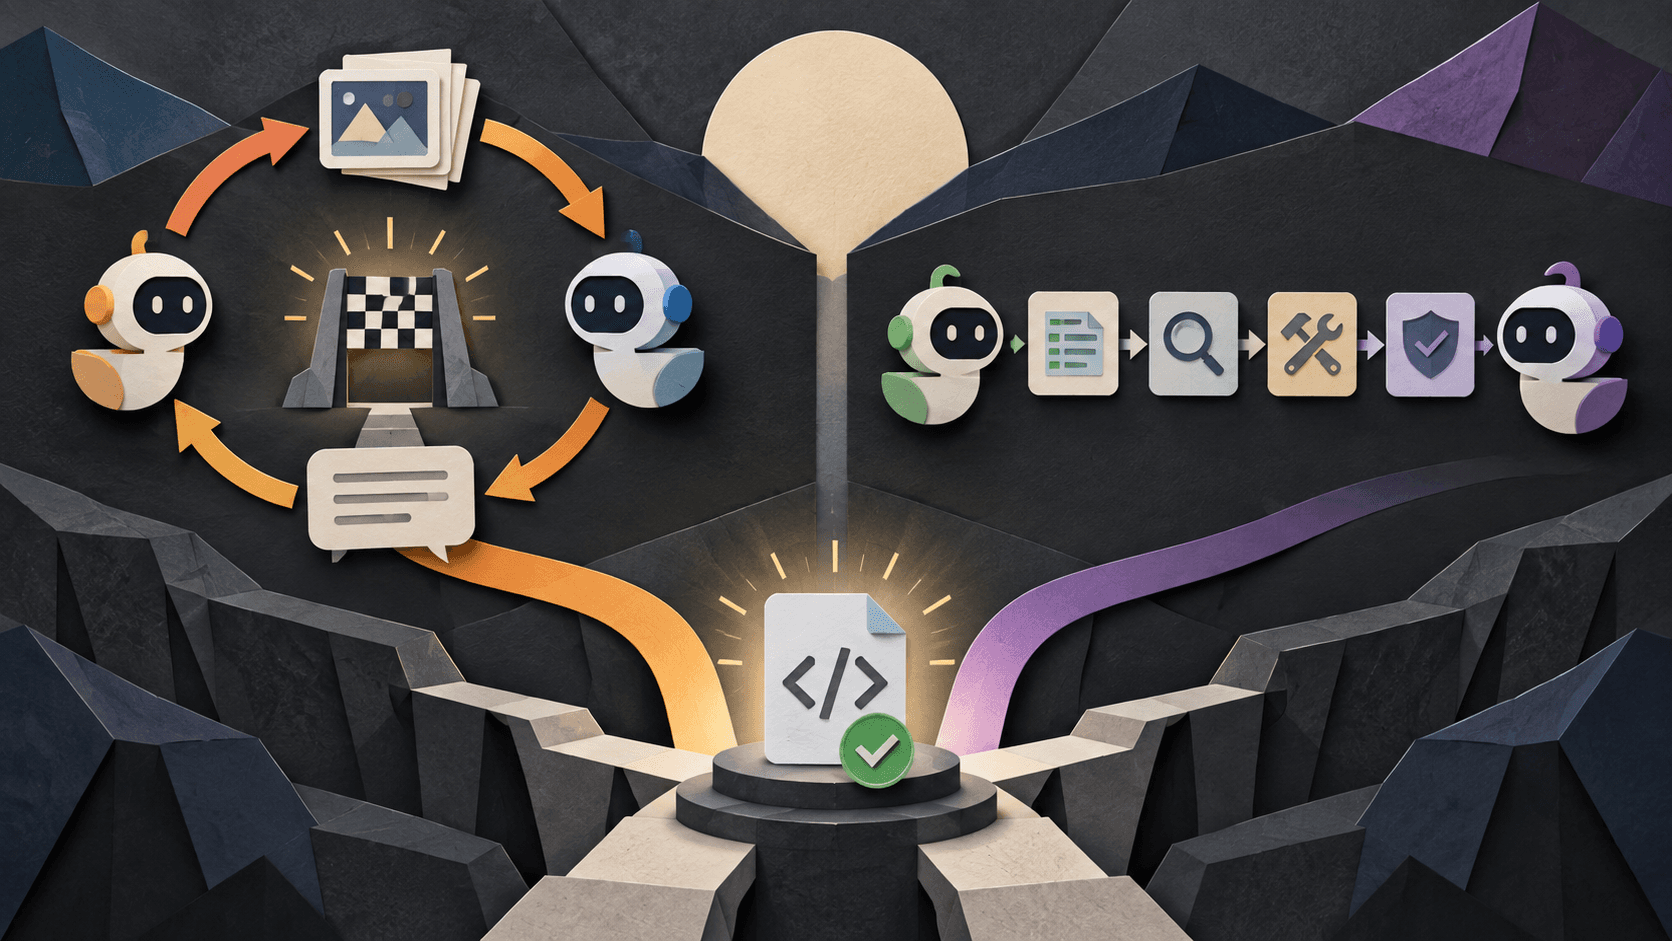
Choose Gauntlet for reference-driven artifact refinement; choose Claudex for bounded software planning, cross-provider review, implementation, and inspection.
A practical comparison of Gauntlet Loop and Claudex Loop across goals, evaluators, workflow structure, setup, cost, stopping rules, and safety controls.
Read guide
AI Implementation for Small Business: Launch Your First Workflow in 30 Days
How to Automate Business Tasks With Zapier and AI in 2026
Best AI for Business Writing in 2026: Emails, Proposals, Reports, and Policies