GPT-6 Astra Long Context and Prompt Caching Cost Guide
Astra's million-token window is useful capacity, not a reason to send every document on every request.
Bottom line
A practical GPT-6 Astra guide to long-context pricing, cache writes and hits, stable prefixes, retrieval, routing, and complete workflow cost.
Editorial accountability
Who checked this guide
- Evaluation type
- Research-based verification
- Last materially checked
- Evidence
- 4 listed sources
Hands-on testing is identified explicitly. Research-based coverage uses cited product documentation and other named sources; it does not imply every paid plan was used. Read the full methodology.
Editorial basis
What this guidance is based on
- Editorial basis
- Source-led analysis
- Primary references
- 4
- Products covered
- 1
- Last checked
- 2026-09-21
Important limits
- • DiscoverAI did not benchmark a production Astra workload for this guide.
- • Rates, limits, caching behavior, and tool charges can change.
In this guide
*This technical guide was checked against OpenAI's model, pricing, caching, and model-selection documentation on September 21, 2026. Prices can change; confirm the live documentation before budgeting.*
Short answer
Use GPT-6 Astra's long context selectively: retrieve the smallest relevant evidence set, keep reusable instructions and references in a stable prompt prefix, and measure total cost per accepted task. Astra supports a 1.05-million-token context window, but requests above 272,000 input tokens move the entire request into higher long-context rates. A large window increases capacity; it does not guarantee that more context improves accuracy.
What Astra actually costs
At standard processing, OpenAI lists Astra at $10 per million input tokens, $1 per million cached input tokens, $12.50 per million cache-write tokens, and $50 per million output tokens. Above the 272,000-input-token threshold, input and cache rates double and output rises to 1.5 times the short-context rate for the full request. Tool calls can add separate charges.
| Workload choice | Cost implication |
|---|---|
| Reuse a matching cached prefix | Cached input can be far cheaper than uncached input |
| Write a prefix once, reuse rarely | The higher cache-write price may not pay back |
| Cross 272K input tokens | The full request uses long-context rates |
| Generate verbose output | Output is the most expensive text-token category |
| Use Batch or Flex | OpenAI lists a 50% processing discount, with different delivery tradeoffs |
Build a cacheable prompt
Place stable material first: system instructions, schemas, tool definitions, policy text, and reference documents that recur across requests. Put changing user input and retrieved evidence later. OpenAI's migration guidance says Astra uses prompt-cache options with a 30-minute TTL. A changed prefix, a low reuse rate, or requests outside the retention window can erase the expected saving.
Do not distort the application merely to create cache hits. Track cache-write tokens, cache-read tokens, hit rate, latency, and accepted-task cost. A cache that reduces token charges but causes stale or irrelevant answers is not an optimization.
Keep long context under control
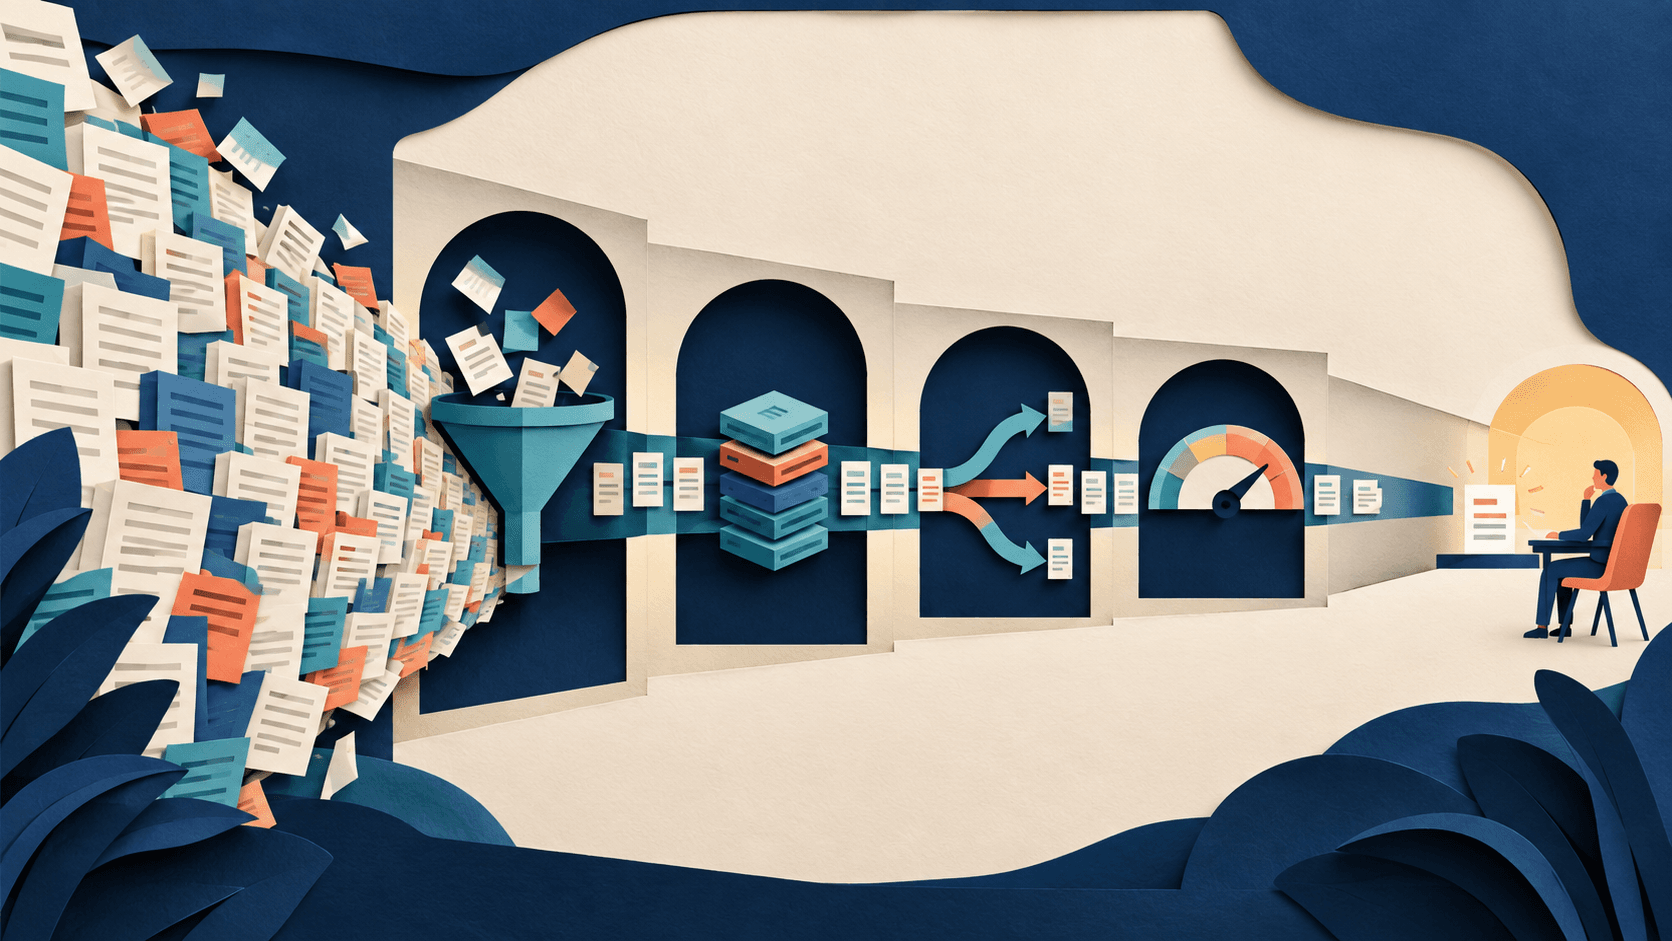
Start with retrieval rather than full-corpus stuffing. Deduplicate documents, strip navigation and boilerplate, preserve source identifiers, and set a hard context budget per task. Test whether a 20K, 100K, and 300K evidence set changes the accepted answer. Long context is appropriate when relationships across a large source set matter; it is wasteful when a narrow lookup can find the evidence.
Route work by difficulty
OpenAI's model-selection guidance recommends reaching the required accuracy first, then optimizing cost and latency. Use Astra to establish a quality ceiling on difficult tasks, but test less expensive models for extraction, classification, rewriting, and other routine work. Preserve a deterministic fallback and pin model snapshots where reproducibility matters.
For base rates and API migration changes, see the [Astra pricing and migration guide](/articles/gpt-6-astra-api-pricing-migration-guide). For the broader launch context, see [why GPT-6 Astra matters](/articles/gpt-6-astra-chatgpt-model-significance-2026).
A cost-control experiment
Replay 50 representative jobs across four variants: full context without caching, retrieved context without caching, retrieved context with caching, and routed Astra-plus-smaller-model traffic. Measure accepted completion, factual errors, reviewer minutes, p50/p95 latency, input, cache write, cache read, output, tool calls, retries, and total cost. Adopt the lowest-cost configuration that still meets the quality target.
Bottom line
The cheapest Astra token is one the application does not send. Retrieval, stable prefixes, cache measurement, concise outputs, and task routing matter more than advertising the maximum context window.
Sources and verification
Product details and claims were checked against the following primary sources.
Frequently asked questions
How large is GPT-6 Astra's context window?
OpenAI lists a 1.05-million-token context window and a 128,000-token maximum output. Practical quality still depends on evidence selection, prompt design, and the task.
When does Astra long-context pricing begin?
OpenAI says requests above 272,000 input tokens use higher rates for the entire request, not only the tokens beyond the threshold.
Does prompt caching always save money?
No. Cache writes cost more than ordinary input, so savings depend on a matching stable prefix being reused enough times within the supported retention period.
Should every difficult request use the full context window?
No. Retrieve and test the smallest sufficient evidence set. Use very long context only when the task genuinely depends on relationships across a large corpus.
Found this useful?
Get the next one in your inbox.
One five-minute briefing a week: a meaningful change, a practical workflow, and a clearer tool decision—already filtered for lean teams.
Free · one email a week · unsubscribe any time
Tools mentioned in this article
ChatGPT
The general-purpose AI assistant that started it all
OpenAI's flagship conversational AI model, powering everything from casual chat to complex reasoning, coding, and creative work.
Read next