How to Anonymize Research Transcripts Before AI Analysis
Deleting names is not enough when roles, places, events, quotations, and linked datasets can still reveal a participant.
Bottom line
A risk-based transcript workflow that protects participants while preserving enough context for useful, auditable analysis.
Editorial accountability
Who checked this guide
- Evaluation type
- Research-based verification
- Last materially checked
- Evidence
- 4 listed sources
Hands-on testing is identified explicitly. Research-based coverage uses cited product documentation and other named sources; it does not imply every paid plan was used. Read the full methodology.
Editorial basis
What this guidance is based on
- Editorial basis
- Source-led analysis
- Primary references
- 4
- Products covered
- 3
- Last checked
- 2026-10-03
Important limits
- • Anonymization is contextual and cannot be guaranteed by a generic checklist.
- • Obtain qualified privacy, legal, and research-ethics advice where required.
Short answer
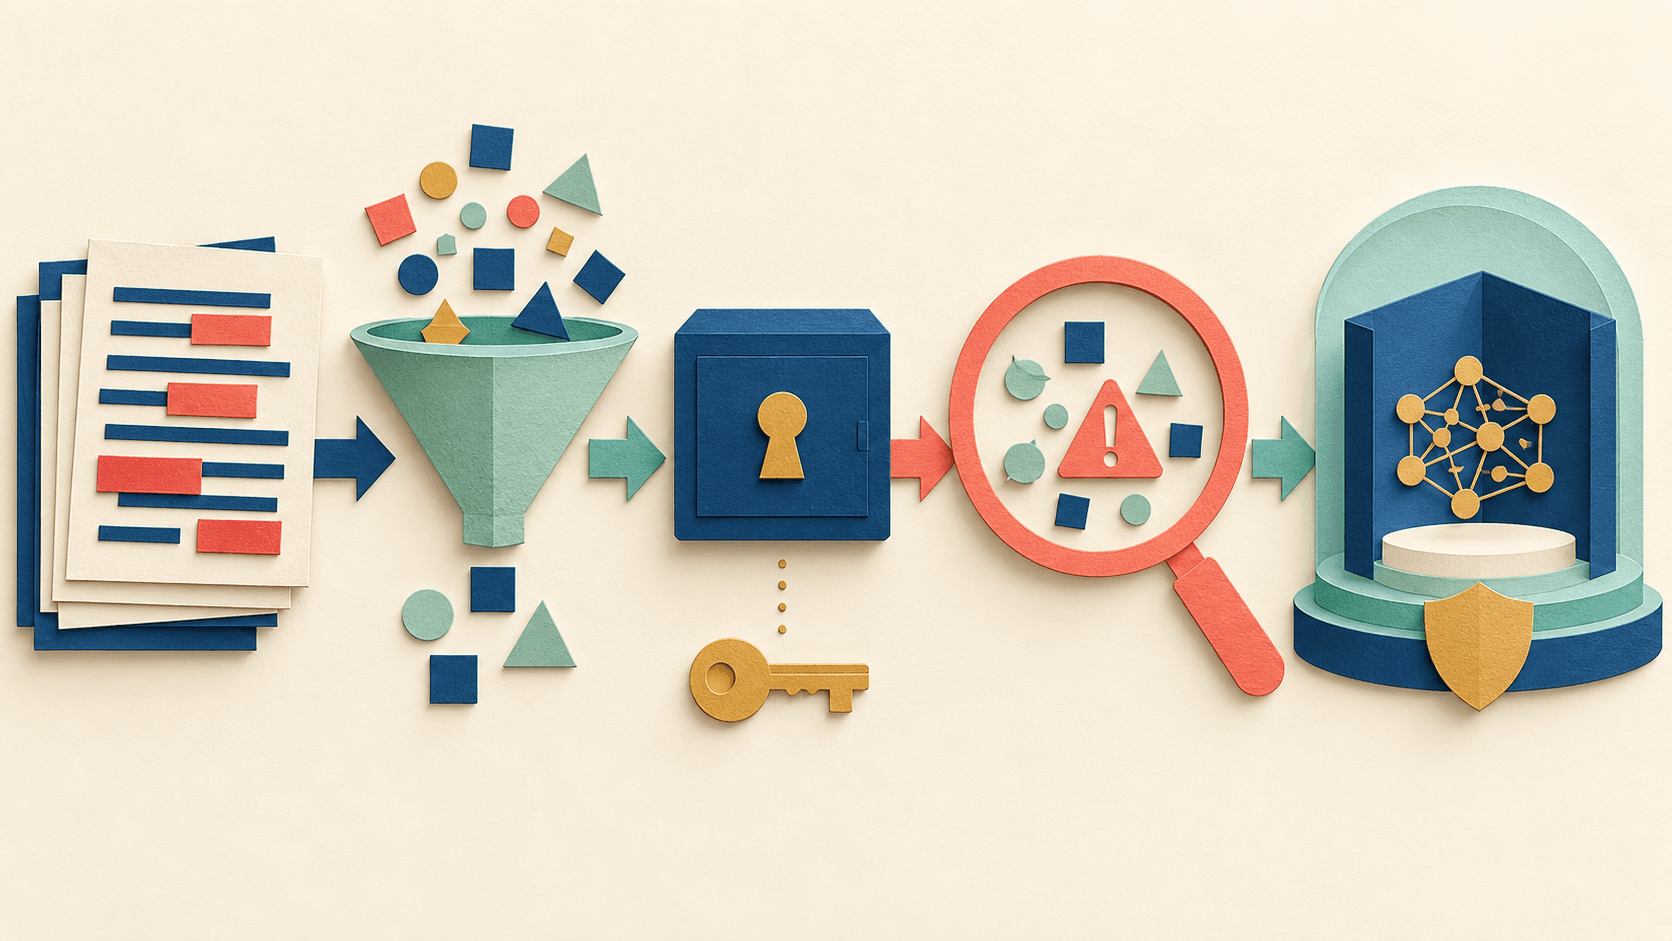
Make a data inventory, remove unnecessary fields, replace direct identifiers, generalize quasi-identifiers, store the re-identification key separately, test whether a motivated recipient could identify someone, and have a second reviewer inspect high-risk passages. Pseudonymized data is still personal data when the key or other linking information exists.
Workflow
Preserve an immutable restricted original. Create a processing copy with stable participant IDs. Mask names, contact details, employers, addresses, exact dates, and account identifiers; generalize rare roles, locations, ages, and events only as far as the analysis allows. Search free text for indirect combinations. Record every transformation and who approved it.
Do not automate the final judgment
Entity detection can find obvious identifiers but misses contextual uniqueness and can erase meaning. Sample every transcript type, inspect quoted passages separately, and reassess risk before wider sharing, publication, or connector access. Confirm retention and deletion across uploads, exports, backups, and downstream AI tools.
Sources and verification
Product details and claims were checked against the following primary sources.
Frequently asked questions
Can AI replace human judgment in transcript anonymization?
No. AI can accelerate retrieval, organization, and first-pass analysis, but an accountable person must verify evidence, context, permissions, and the final decision.
What should a team measure?
Measure source accuracy, correction time, missed counterevidence, permission behavior, export quality, and cost per accepted deliverable—not output volume.
What data is safe to use?
Only data covered by the participant notice, contract, organizational policy, and vendor terms. Remove unnecessary identifiers and keep the original evidence outside the model workflow.
What is the minimum audit trail?
Keep the source manifest, prompt and model record, output, reviewer corrections, approval decision, and deletion or retention record.
Tools mentioned in this article
Condens
Structured qualitative analysis and a governed research repository
Condens organizes sessions, highlights, tags, findings, repository search, and AI-assisted analysis for research teams that need reusable evidence.
Looppanel
AI-assisted interview analysis and research repository for source-linked insights
Looppanel combines recording, transcription, notes, tagging, synthesis, clips, repository search, and controlled AI access for interview-heavy research teams.
ChatGPT
The general-purpose AI assistant that started it all
OpenAI's flagship conversational AI model, powering everything from casual chat to complex reasoning, coding, and creative work.
Read next