In this guide
Short answer
AI can help label passages, cluster codes, retrieve similar excerpts, and test a codebook across a large corpus. It should not silently choose the unit of analysis, collapse minority views, or turn linguistic similarity into an interpreted theme. Keep a versioned codebook, calibrate on a diverse sample, preserve source links, review disagreement and negative cases, and record every material merge or rename.
Free workflow pilot checklist
Test the workflow before you buy the tool.
Use our buyer checklist to plan a task, assign a reviewer and track time saved. You’ll also receive the weekly AI briefing.
Start with an analysis plan
State whether the study is inductive, deductive, or hybrid; what counts as a coding unit; whether multiple codes may overlap; how participant and segment context will be retained; and who resolves disagreements. Define what the dataset can and cannot answer before the model sees it.
Build codebook version 0.1
For each code, record a label, definition, include rule, exclude rule, boundary cases, positive example, and counterexample. Use provisional language. Early codes are tools for thinking, not discovered facts.
Calibrate on a deliberately varied sample
Select material across participant segments, session quality, sentiment, and likely edge cases. Have at least one researcher code it independently, then compare the AI pass. Examine false positives, missed passages, overly broad codes, fragmentation, and whether the model treats frequency as importance.
Scale with review queues
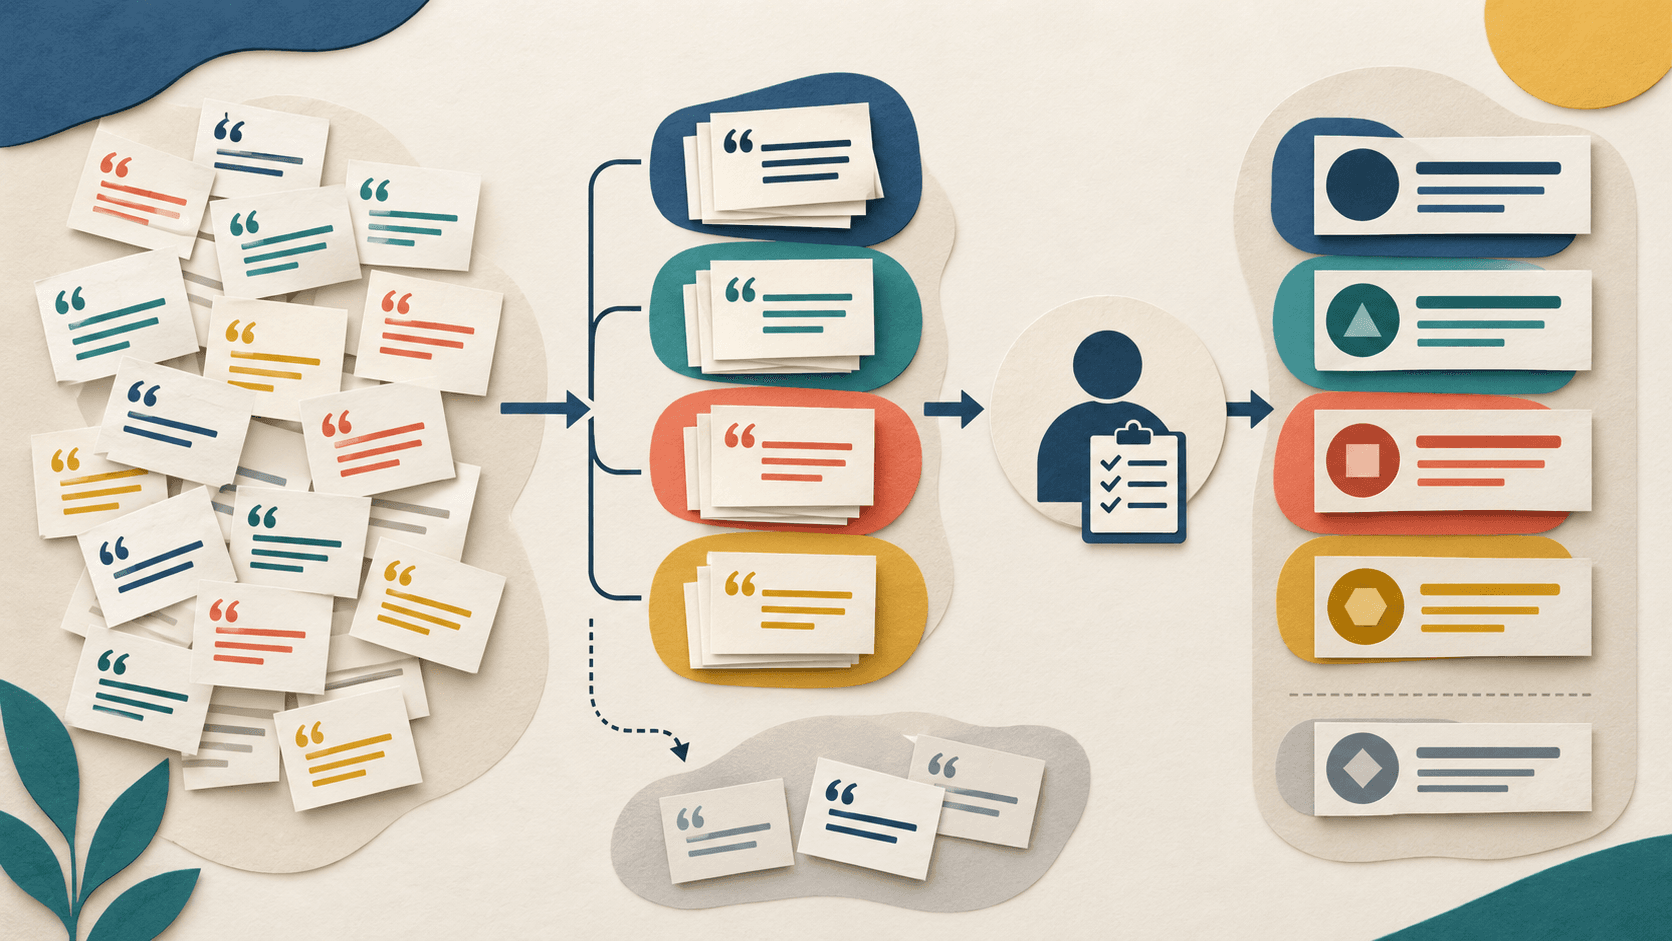
Let the system propose codes with exact source references and confidence or ambiguity notes. Route new codes, low-confidence passages, sensitive material, contradictions, and high-impact claims to human review. Freeze the model and prompt during a comparable batch when consistency matters.
Move from codes to themes carefully
A theme is an interpreted pattern relevant to the research question—not merely a cluster of similar words. Review internal coherence, distinction from other themes, coverage, counterevidence, segment differences, and the story the theme tells. Keep an explicit trail from theme to codes to excerpts to sources.
Audit for systematic bias
Check whose language the codebook privileges, whether translated or indirect speech is under-coded, whether minority experiences disappear, and whether the tool overweights polished or lengthy responses. Compare results across ordering, prompts, reviewers, or tools when a conclusion is consequential.
Deliverables
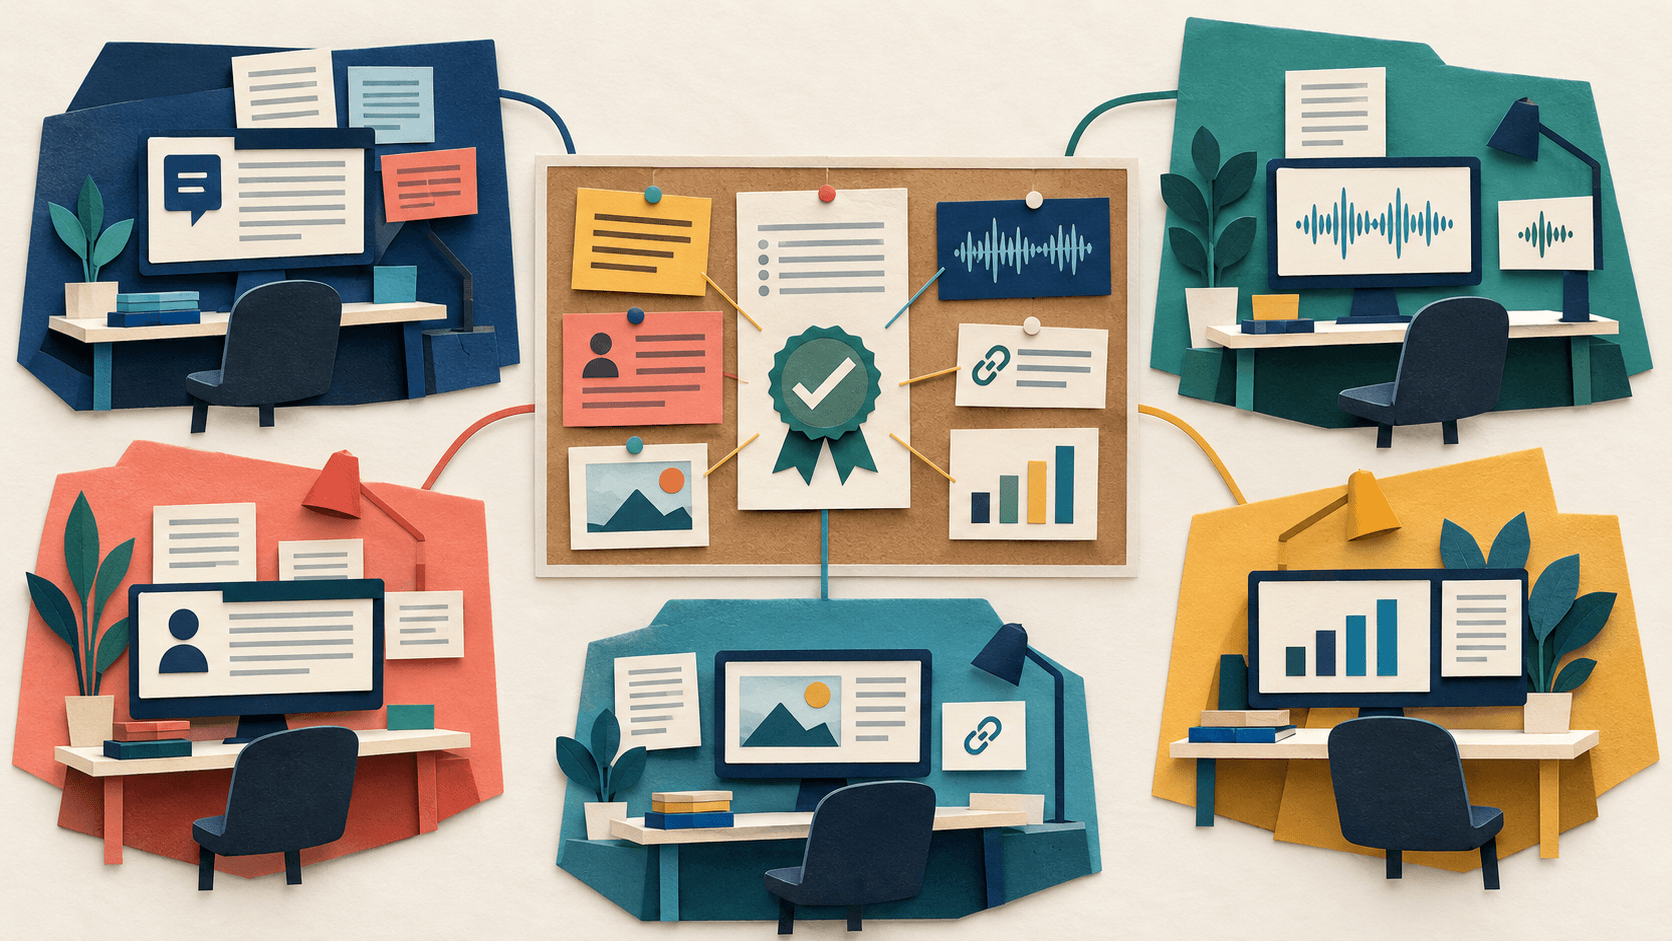
Retain the analysis plan, dataset manifest, consent boundary, codebook versions, prompt and model record, sampled validation results, disagreement log, theme map, negative cases, source-linked findings, and final limitations. That packet makes the work reproducible enough to challenge and update.
Transparency
How this guide was checked
About this article
How this article was prepared
- Evaluation type
- Source-based research
- Last reviewed
- Evidence
- 4 listed sources
We label hands-on testing separately. Research-based articles draw on product documentation and other cited sources, rather than direct use of every plan. Read the full methodology.
Editorial basis
Sources and testing
- Editorial basis
- Source-based research
- Primary references
- 4
- Products covered
- 3
- Last checked
- 2026-10-02
Important limits
- • There is no single correct thematic-analysis procedure for every epistemological or research tradition.
- • Tool output quality depends on the dataset, language, model, prompt, coding unit, and reviewer expertise.
Sources and references
References cited by this article. Check the original source for scope, dates and current terms.
Frequently asked questions
Can AI perform thematic analysis automatically?
It can propose codes and clusters, but researchers must define the analytic approach, interpret themes, examine context and negative cases, and own the conclusions.
What is a qualitative codebook?
It is a versioned set of code labels, definitions, boundaries, examples, and decision rules used to make coding more explicit and reviewable.
Should code frequency determine importance?
No. Frequency can be useful context, but relevance, intensity, consequence, research questions, sampling, and contradictory evidence also shape interpretation.
How do I validate AI coding?
Use a diverse calibration sample, compare against human coding, inspect false positives and misses, review disagreement, test negative cases, and retain exact source links.
Tools mentioned in this article
ChatGPT
The general-purpose AI assistant that started it all
OpenAI's flagship conversational AI model, powering everything from casual chat to complex reasoning, coding, and creative work.
Claude
Anthropic's thoughtful, safety-focused AI with exceptional long-form reasoning
Claude excels at deep analysis, long-form writing, and nuanced reasoning. Built by Anthropic with a focus on safety and helpfulness.
NotebookLM
A source-grounded Google research workspace for asking questions and generating overviews from a controlled source set
NotebookLM is a strong research companion when you already have a defined source library, but citations, source completeness, privacy, and plan limits still require human review.
Read next