Gemini 3.8 Flash ‘Works Harder’—Measure the Cost of the Finished Task
More reasoning can improve a difficult result while increasing latency and tool activity; the useful unit is an accepted outcome, not a token or benchmark alone.
Bottom line
Google positions Gemini 3.8 Flash as a more diligent workhorse for reasoning, software engineering, and agents. Buyers should test the whole task economics.
Editorial accountability
Who checked this guide
- Evaluation type
- Research-based verification
- Last materially checked
- Evidence
- 4 listed sources
Hands-on testing is identified explicitly. Research-based coverage uses cited product documentation and other named sources; it does not imply every paid plan was used. Read the full methodology.
Editorial basis
What this guidance is based on
- Editorial basis
- Source-led analysis
- Primary references
- 4
- Products covered
- 1
- Last checked
- 2026-09-29
Important limits
- • No independent controlled benchmark or production migration.
- • Model availability, rates, limits, and behavior can change.
In this guide
What changed
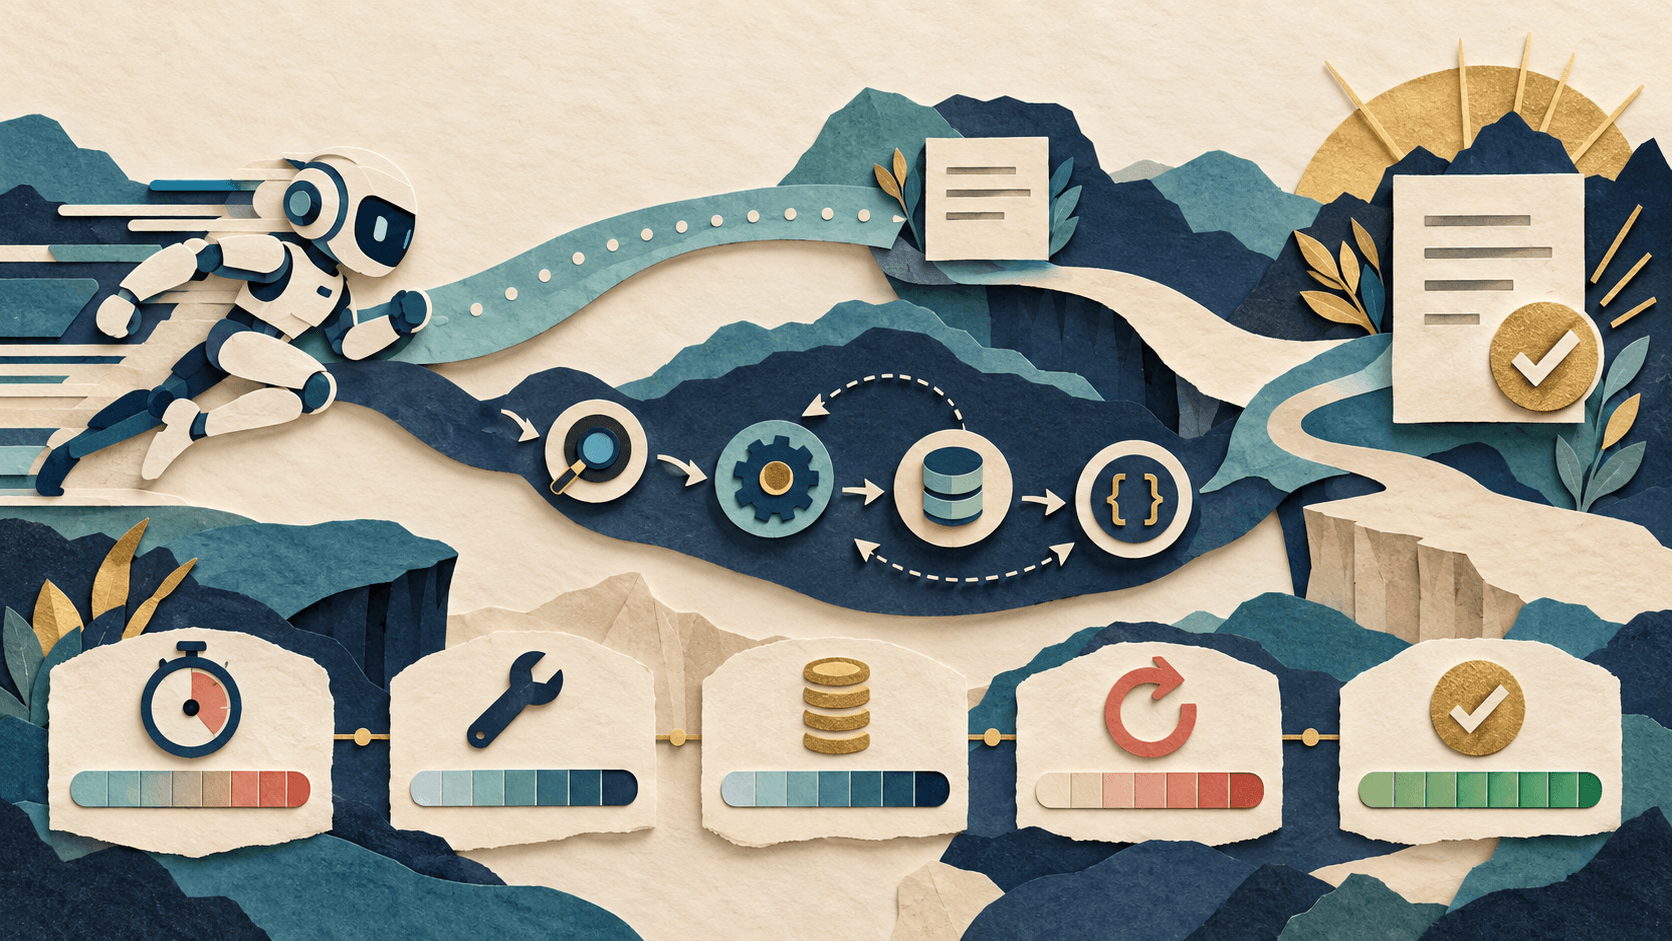
Google describes Gemini 3.8 Flash as its most capable Flash workhorse, with gains in software engineering, agentic tasks, and specialized multistep reasoning. The important implementation detail is the company's explanation: the model "works harder" by taking additional reasoning steps and calling tools iteratively. That may improve difficult outcomes, but it can also change latency, tokens, tool charges, side effects, and failure recovery.
Why price per token is incomplete
A lower unit price can still produce an expensive task if the model uses a long context, makes many tool calls, retries, or requires heavy review. A more diligent model can also be cheaper overall if it finishes correctly on the first attempt. Compare total cost per accepted task: model usage, search or tool charges, infrastructure, retries, reviewer minutes, reversals, and failure impact.
Benchmark claims are a starting point
Google says 3.8 Flash improves on 3.7 Flash and can approach higher-cost frontier models on selected work. Provider evaluations and showcase applications help identify candidate workloads; they do not establish reliability in a buyer's repository, permissions, data, tools, region, or risk tolerance.
Run a matched replay
Select at least 100 real tasks across easy, typical, and difficult bands. Freeze prompts, tools, data, and acceptance rules. Compare the current model with 3.8 Flash on accepted-task rate, severe failures, p50 and p95 latency, input and output tokens, reasoning effort where exposed, tool calls, retries, reviewer time, and cost per accepted result. Keep a rollback path.
Watch the tool boundary
Iterative tool use expands the opportunity for duplicate writes, stale reads, runaway searches, permission overreach, and partial completion. Use idempotency keys, budgets, timeouts, least privilege, approval for consequential actions, and explicit terminal states. A model that keeps trying should still know when to stop.
Bottom line
Gemini 3.8 Flash is interesting because Google is optimizing a fast model for deeper work, not merely shorter responses. Adopt it when matched testing shows better accepted outcomes at an acceptable full-task cost and failure tail—not because one benchmark or per-token rate looks attractive.
Sources and verification
Product details and claims were checked against the following primary sources.
Frequently asked questions
What is Gemini 3.8 Flash?
Google describes it as a fast workhorse model improved for complex reasoning, software engineering, agentic tasks, multimodal work, and iterative tool use.
Does more reasoning always cost more?
Not necessarily. It can increase tokens, latency, or tool calls, but may reduce retries and corrections. Measure the full cost per accepted task.
Should teams replace 3.7 Flash immediately?
No. Replay representative work with fixed acceptance criteria, inspect serious failures and total economics, and retain a rollback path before moving production traffic.
Which metrics matter for an agent workload?
Track accepted-task rate, severe failures, p50 and p95 latency, tokens, tool calls, retries, reviewer time, reversals, and cost per accepted result.
Tools mentioned in this article
Google Gemini
Google's deeply integrated AI assistant with unmatched access to Google's ecosystem
Gemini combines powerful AI with Google's vast data ecosystem — Search, Gmail, Docs, YouTube, and more — for a uniquely integrated experience.
Read next
Recommended for you
Meta Muse Review 2026: Features, Privacy, and Risks
Muse can do work across connected services, but the buying decision turns on permissions, reliability, auditability, and recovery—not the demo task list.
Meta Muse is a promising action-taking personal agent, provided users grant authority gradually and test mistakes, approvals, revocation, and recovery before trusting consequential work.
Read guide
TypeSafe AI Review 2026: Is Jev Ready for Production?
AI Implementation for Small Business: Launch Your First Workflow in 30 Days
Best AI for Business Writing in 2026: Emails, Proposals, Reports, and Policies