Barclays Is Scaling Claude—The Missing Metric Is Accepted Work
Sixteen thousand users and 120,000 routed emails a day show adoption; they do not yet show accuracy, customer outcomes, control quality, or net value.
Bottom line
Barclays is expanding Claude across a regulated bank. The announcement offers unusually concrete usage volumes, but buyers still need error, override, outcome, and cost evidence.
Editorial accountability
Who checked this guide
- Evaluation type
- Research-based verification
- Last materially checked
- Evidence
- 4 listed sources
Hands-on testing is identified explicitly. Research-based coverage uses cited product documentation and other named sources; it does not imply every paid plan was used. Read the full methodology.
Editorial basis
What this guidance is based on
- Editorial basis
- Source-led analysis
- Primary references
- 4
- Products covered
- 1
- Last checked
- 2026-10-01
Important limits
- • The reported usage figures come from Anthropic's partnership announcement and were not independently audited by DiscoverAI.
- • The announcement does not publish controlled accuracy, customer-outcome, incident, or total-cost results for the named workflows.
In this guide
Short answer
Barclays and Anthropic announced on October 1, 2026 that the bank is expanding Claude across knowledge assistance, client-email operations, software development, legacy modernization, and cybersecurity. The strongest part of the announcement is its operational scale: Barclays says more than 16,000 colleagues use a retrieval-augmented knowledge assistant that has handled over one million searches, while a Global Markets workflow processes about 120,000 emails each day. Those are meaningful adoption measures—not proof of accuracy, safer decisions, faster resolution, or positive return.
Three deployments, three different risk models
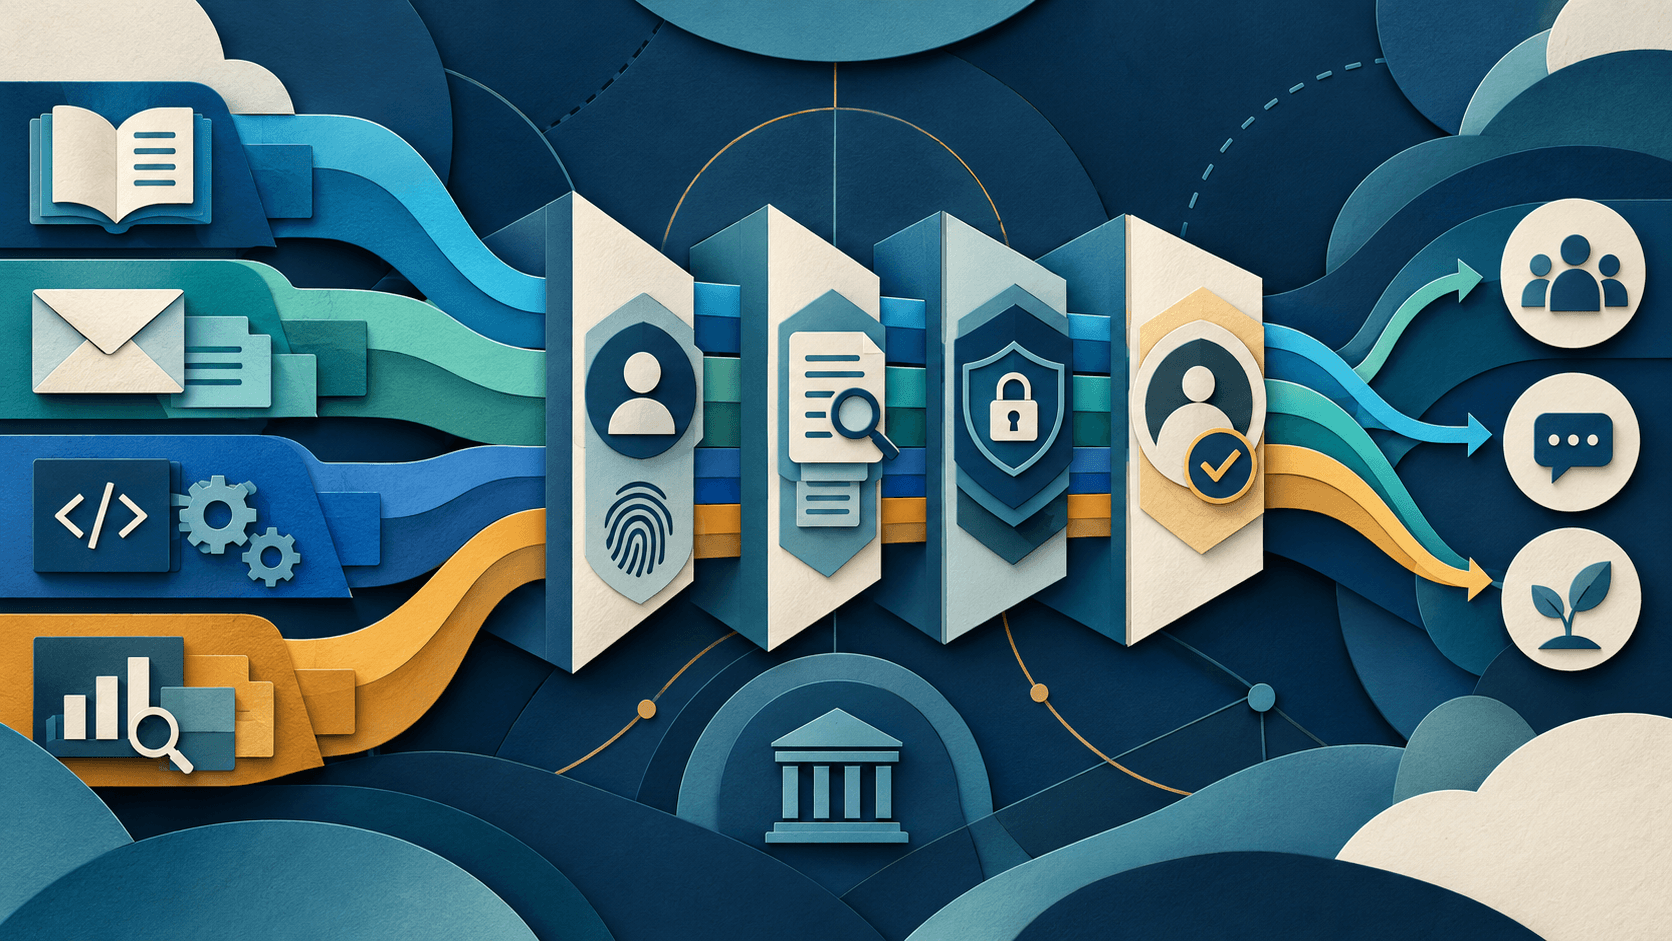
Knowledge retrieval must return current, entitled, traceable information and abstain when evidence is weak. Email classification must preserve messages, recognize urgency, route correctly, and expose uncertainty without silently dropping work. Coding agents can change files, run commands, and influence production systems, so they require isolated execution, least privilege, protected branches, tests, human approval, and rollback. One umbrella AI policy is not enough.
Adoption is not an outcome
Searches, emails, users, and developer coverage describe reach. A useful evaluation also reports answer acceptance, citation validity, stale-content errors, incorrect routing, human overrides, customer-resolution time, reopened cases, escaped defects, security findings, reviewer effort, incident rates, and fully loaded cost. Report distributions and severe failures, not only averages.
What a regulated buyer should request
Ask for the exact model and hosting path; retrieval sources and entitlement enforcement; data retention and training terms; identity and audit controls; testing by use case; confidence and abstention behavior; human escalation; incident response; vendor-change management; and evidence that controls operate under load. Separate vendor claims from bank-measured results and publish the measurement window.
Bottom line
Barclays provides a useful case study because it names live workflows and volumes rather than announcing a vague partnership. The next credible milestone is outcome evidence: accepted work, corrected failures, customer effects, risk events, and total cost for each workflow. Other enterprises should copy the measurement discipline, not merely the product choice.
Sources and verification
Product details and claims were checked against the following primary sources.
Frequently asked questions
What did Barclays announce with Anthropic?
Barclays is expanding Claude across employee knowledge search, Global Markets email processing, software engineering, legacy modernization, and cybersecurity.
How widely is Claude already used at Barclays?
Anthropic says more than 16,000 colleagues use the knowledge assistant, which has handled over one million searches, and an email workflow processes about 120,000 messages daily.
Do those volumes prove the AI works well?
No. They show usage and throughput. Accuracy, overrides, severe errors, customer outcomes, risk incidents, reviewer effort, and total cost require separate evidence.
What should another bank measure?
Measure accepted outputs, citation validity, routing errors, abstentions, human corrections, resolution time, reopened work, escaped defects, incidents, and fully loaded cost by workflow.
Tools mentioned in this article
Claude
Anthropic's thoughtful, safety-focused AI with exceptional long-form reasoning
Claude excels at deep analysis, long-form writing, and nuanced reasoning. Built by Anthropic with a focus on safety and helpfulness.
Read next