The decision
Should you choose BAML?
BAML earns a pilot when typed LLM calls are a real engineering boundary rather than a demo convenience. The open-source core makes evaluation inexpensive. Keep domain validation, source grounding, monitoring, and human review around high-consequence outputs.
Best for
Developers shipping structured LLM extraction or classification; Teams switching among model providers.
Choose something else if
Simple chat prototypes with no structured contract; Teams unwilling to add a domain-specific language
Evidence
Editorial research pending · 8.2/10
Pricing checked
See current vendor pricing · Sep 11, 2026
Free access is available, with limits.
Yes. Core BAML is open source and the listed Free tier supports one developer.
In this guide
Short answer
BAML is worth testing when structured LLM output is production-critical and JSON prompts plus ad hoc repair code have become brittle. Typed functions, generated clients, validation, and test tooling can make contracts clearer across model providers. BAML reduces parsing friction; it cannot guarantee that a semantically wrong answer satisfying the schema is correct.
Free buyer comparison checklist
Compare this tool before committing.
Use the buyer checklist to compare two tools on the same tasks, including quality, review time and total cost. Get the weekly top 5 AI tools, one practical workflow and one way to reduce AI spending.
Best for
- Developers shipping structured LLM extraction or classification
- Teams switching among model providers
- Codebases that need typed, testable prompt contracts
Look elsewhere if
- Simple chat prototypes with no structured contract
- Teams unwilling to add a domain-specific language
- High-stakes decisions relying only on schema validation
What BAML verifiably does
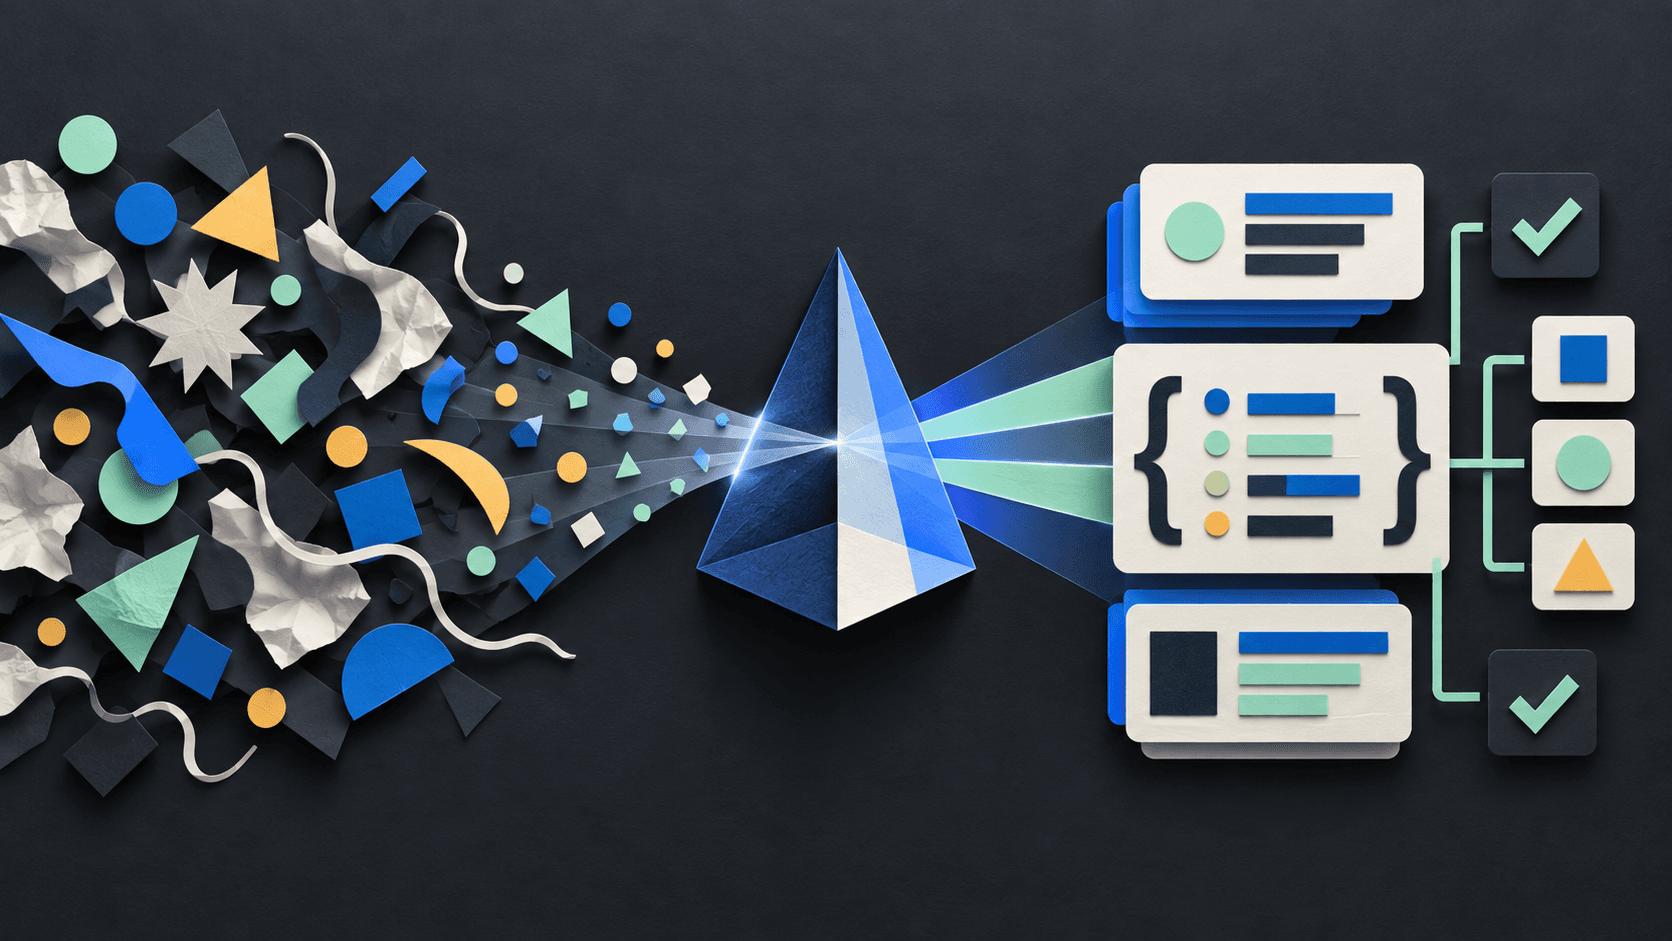
BAML defines LLM functions with typed inputs and outputs, generates TypeScript, Python, Ruby, Go, and other clients, and supports streaming partially structured results. Its parser and runtime target resilient structured output, while editor tooling and tests make prompts and schemas reviewable in code.
Important limitations
A valid object may still contain invented facts, unsafe values, or logically inconsistent fields. Adopting a domain-specific language adds build tooling and a new abstraction to maintain. Teams must test model changes, parsing edge cases, provider failures, streaming states, and business invariants beyond schema validity.
BAML pricing
Boundary lists a $0 Free tier for one developer with unlimited BAML schemas and local development, a Team tier at $25 per month with collaboration and advanced validation, and custom Enterprise terms for on-premises deployment, SSO/SAML, audit logs, SLAs, and support. Model-provider inference remains a separate cost. Reviewed September 11, 2026.
A fair buyer test
Create a 1,000-case extraction set with malformed source text, missing fields, long documents, prompt injection, enum ambiguity, nested arrays, multilingual inputs, and provider timeouts. Compare BAML with the current JSON-schema path across three models. Measure parse success, semantic accuracy, retry rate, latency, token cost, developer repair code, and incorrect-but-valid outputs.
Final verdict
BAML earns a pilot when typed LLM calls are a real engineering boundary rather than a demo convenience. The open-source core makes evaluation inexpensive. Keep domain validation, source grounding, monitoring, and human review around high-consequence outputs.
This is a research-based product assessment, not a claim of hands-on long-term testing. Product, pricing, privacy, security, and usage claims were checked against the first-party sources below on September 11, 2026. Verify current terms and run the proposed test with approved data before adoption.
Transparency
How this guide was checked
Editorial accountability
Who checked this guide
- Evaluation type
- Hands-on evaluation
- Last materially checked
- Evidence
- 4 listed sources
Hands-on testing is identified explicitly. Research-based coverage uses cited product documentation and other named sources; it does not imply every paid plan was used. Read the full methodology.
Editorial freshness
Pricing and material product claims were checked September 11, 2026.
Review evidence
What this guidance is based on
- Review type
- Research-based product assessment
- Material review date
- September 11, 2026
- Evidence
- Current first-party product, pricing, documentation, privacy, and security material
- Buyer test
- Controlled quality, cost, permissions, privacy, reliability, and failure-path evaluation
Important limits
- • DiscoverAI did not complete the proposed long-term paid deployment for this review.
- • Features, prices, limits, security controls, and provider data paths can change; verify the linked first-party pages before purchase.
Standardized benchmark coverage
How this review maps to the research benchmark
Citation accuracy
Not applicableThe reviewed workflow does not produce source-grounded research answers, so a citation score would be misleading.
Read protocol v2026.10-v1 →Thematic analysis
Not applicableThe reviewed workflow is not qualitative evidence analysis, so a thematic-analysis score would be misleading.
Read protocol v2026.10-v1 →Eligibility is not a product score. DiscoverAI publishes results only after output collection, blinded adjudication, reproducibility checks, and severe-error review.
Open the optional evaluation worksheet
Reusable trial worksheet
Test BAML before you commit
Turn this review’s buyer test into evidence. Your entries autosave only in this browser and are never added to shared shortlist links.
Confirm the tool meets every must-have workflow and stakeholder requirement.
Review starting point: Developers shipping structured LLM extraction or classification; Teams switching among model providers; Codebases that need typed, testable prompt contracts
Run the same representative work you would use in production; do not score a polished demo.
Review starting point: Create a 1,000-case extraction set with malformed source text, missing fields, long documents, prompt injection, enum ambiguity, nested arrays, multilingual inputs, and provider timeouts. Compare BAML with the current JSON-schema path across three models. Measure parse success, semantic accuracy, retry rate, latency, token cost, developer repair code, and incorrect-but-valid outputs.
Calculate the effective cost per accepted result, including usage, review, corrections, and required add-ons.
Review starting point: Boundary lists a $0 Free tier for one developer with unlimited BAML schemas and local development, a Team tier at $25 per month with collaboration and advanced validation, and custom Enterprise terms for on-premises deployment, SSO/SAML, audit logs, SLAs, and support. Model-provider inference remains a separate cost. Reviewed September 11, 2026.
Define an acceptance threshold, test known answers and edge cases, and record every correction.
Review starting point: Editorial quality signals: features 4.3/5; AI quality 4.1/5. Validate these signals in your own work.
Verify what data enters the product, who can access it, how long it is retained, and whether it trains models.
Review starting point: Use approved low-risk data first. Check roles, consent, deletion, subprocessors, model-training settings, and the contract—not only the marketing page.
Test the real handoffs, permissions, failure states, and export path your team depends on.
Review starting point: OpenAI, Anthropic, Google, AWS Bedrock, TypeScript, Python
Record training, governance, reliability, accessibility, ownership, and change-management risks before rollout.
Review starting point: Adds a new language and build step; Schema validity is not factual correctness; Inference costs remain separate
Loading saved worksheet… · private to this device or your optional account
Community evidence
How verified users put BAML to work
Structured, editor-moderated experience—not star ratings. This complements our independent review and never changes its score.
No approved community evidence yet. Be the first verified user to contribute.
Community choice
Recommend BAML
Loading weekly votes…
One vote per verified account per tool, counted for seven days. Return after your vote expires to support again. Community votes influence homepage trends, never editorial ratings. Voting does not subscribe you to emails.
Sources and references
References cited by this article. Check the original source for scope, dates and current terms.
Frequently asked questions
What is BAML?
BAML is a domain-specific language and runtime for defining typed LLM functions and turning model responses into structured application data.
Is BAML free?
The core is open source and Boundary lists a $0 individual tier; Team is listed at $25 monthly and Enterprise is custom.
Does BAML include model inference?
No. BAML orchestrates calls to supported model providers, whose inference charges and data terms remain separate.
Does typed output eliminate hallucinations?
No. Types improve structure and validation, but a model can still return a plausible, schema-valid answer that is factually wrong.
Recommended tool
Use BAML if this workflow fits your team
Open-source typed LLM function layer
Tools mentioned in this article
BAML
Define typed LLM functions and validate structured output across models
BAML is an open-source domain-specific language and runtime from Boundary for defining typed LLM functions, generating client code, parsing structured outputs, and testing prompts across providers.
Read next