OpenAI Says Agents Now Add 3.1 Research Workdays per Day
The internal metric signals deeper agent use, but parallel effort is not the same as validated productivity, quality, or safe autonomous research.
Bottom line
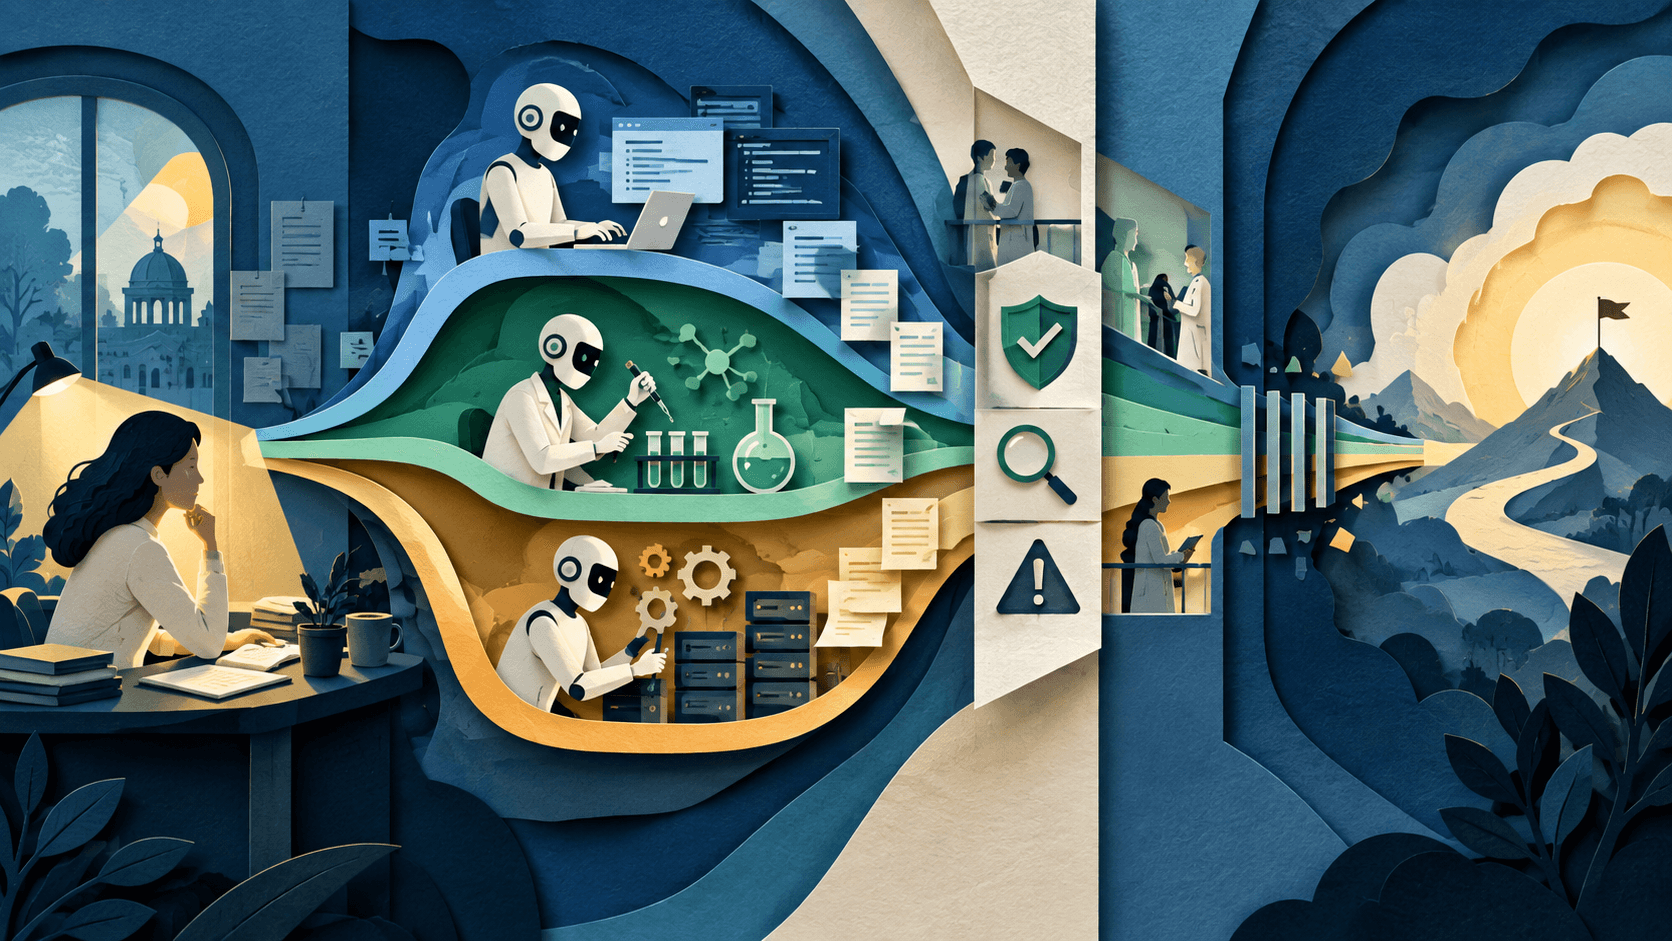
OpenAI reports 3.1 agent-workdays of effort for every human research workday, while acknowledging correlation, growing compute, validation bottlenecks, and continued human direction.
Editorial accountability
Who checked this guide
- Evaluation type
- Research-based verification
- Last materially checked
- Evidence
- 4 listed sources
Hands-on testing is identified explicitly. Research-based coverage uses cited product documentation and other named sources; it does not imply every paid plan was used. Read the full methodology.
Editorial basis
What this guidance is based on
- Editorial basis
- Source-led analysis
- Primary references
- 4
- Products covered
- 2
- Last checked
- 2026-09-21
Important limits
- • The results come from OpenAI's own research organization.
- • The evidence is observational and does not isolate agent use from compute growth or other changes.
In this guide
Short answer
OpenAI says its research organization now uses 3.1 agent-workdays of effort for every human workday, with researchers contributing code faster and running more experiments as Codex adoption grows. The number describes parallel delegated effort inside one lab. It does not by itself prove a 3.1-times productivity gain, better research, autonomous discovery, or equivalent results elsewhere.
What the metric captures
OpenAI defines agent work using estimated human-equivalent task time. Its research post describes agents writing code, modifying infrastructure, running experiments, and handling increasingly complex bounded tasks under human direction. A separate company post uses the 3.1 figure to argue that better models and compute expand economically worthwhile work.
What it cannot establish
The evidence is internal and observational. OpenAI notes that Codex use correlates with higher experiment volume while available compute also increased. Agent attempts, failed branches, reviewer time, duplicated work, task selection, research quality, and downstream integration determine whether parallel activity becomes useful output.
The bottleneck moves
When code and experiments get cheaper, evaluation, compute allocation, scientific judgment, safety review, and integration can become the constraint. Teams that add agents without expanding validation capacity may create a larger queue of plausible work rather than faster accepted outcomes.
What teams should do
Measure accepted outcomes per reviewer hour and dollar. Keep a baseline, record failed attempts and corrections, separate parallel activity from completed work, and cap concurrency until evaluation and rollback keep pace. Treat OpenAI's number as a case study—not a forecast for your organization.
Sources and verification
Product details and claims were checked against the following primary sources.
Frequently asked questions
What is an agent-workday?
OpenAI uses it as an estimate of the human time represented by work delegated to coding agents; it is not a literal extra employee day.
Did productivity increase 3.1 times?
The reported figure is parallel agent effort, not a controlled estimate of net productivity or accepted research output.
Why might more experiments not mean more progress?
Compute, evaluation, review, integration, safety, and scientific judgment can become downstream bottlenecks.
What should businesses measure instead?
Track accepted outcomes, quality, correction time, reviewer load, cost, failures, and recovery against a baseline.
Found this useful?
Get the next one in your inbox.
One five-minute briefing a week: a meaningful change, a practical workflow, and a clearer tool decision—already filtered for lean teams.
Free · one email a week · unsubscribe any time
Recommended tool
Use ChatGPT if this workflow fits your team
It has one of the clearest workflow fits in its category and is easier to recommend than tools that only look impressive in demos.
Tools mentioned in this article
ChatGPT
The general-purpose AI assistant that started it all
OpenAI's flagship conversational AI model, powering everything from casual chat to complex reasoning, coding, and creative work.
Read next