How to Evaluate an AI Coding Agent: A Five-Task Test
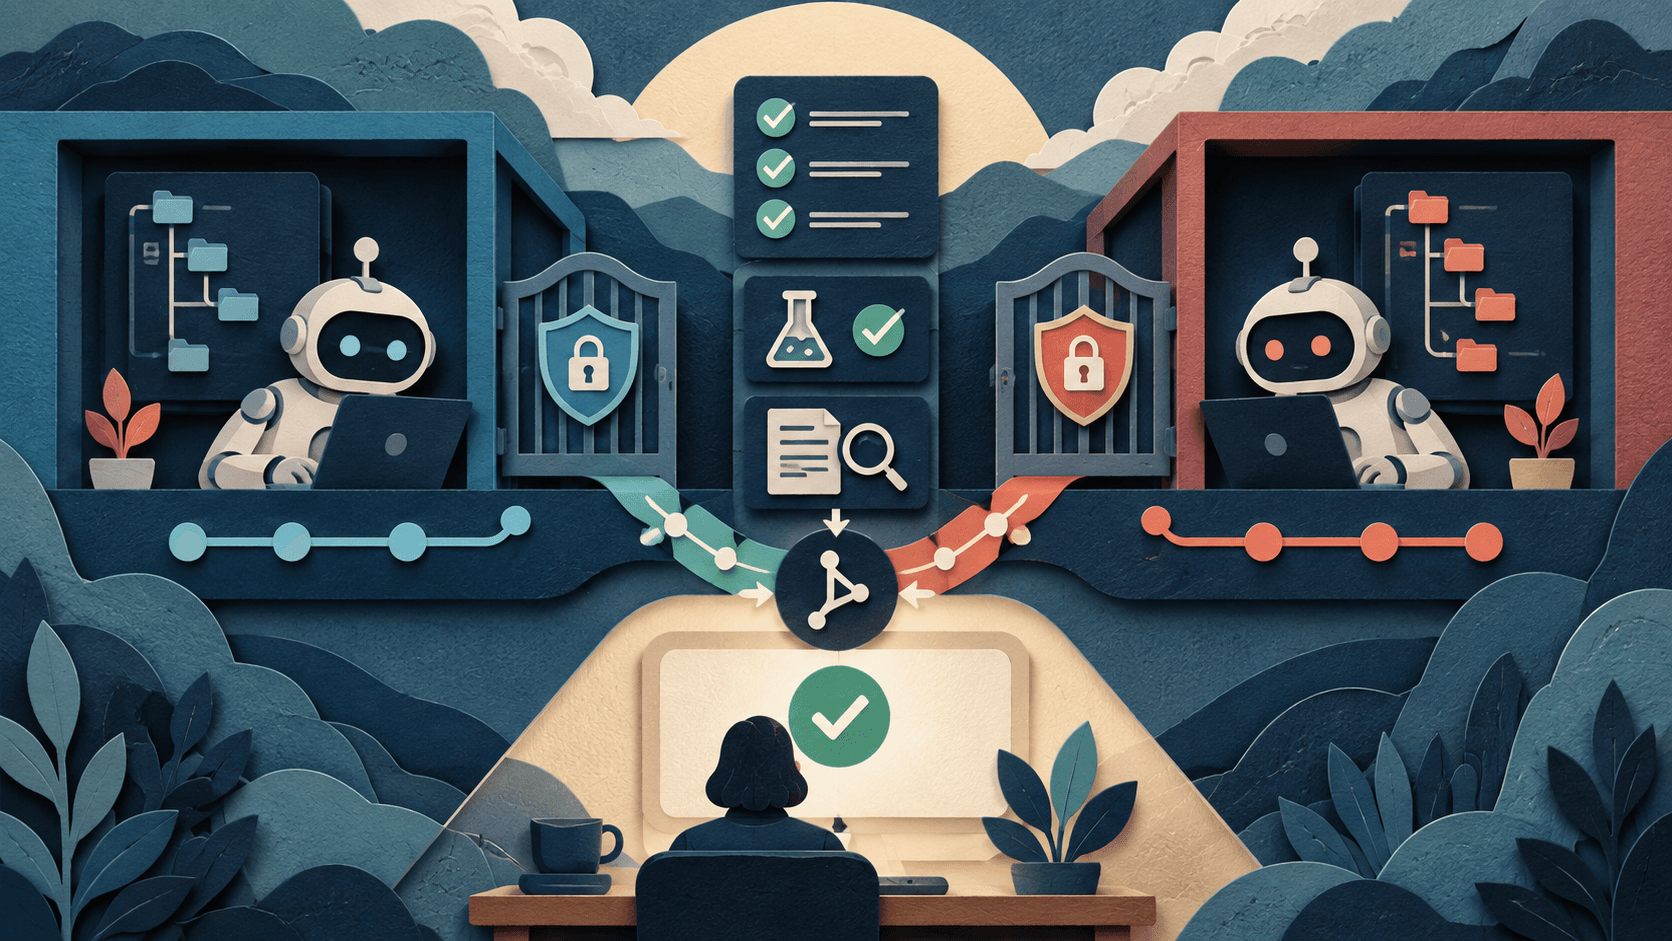
A fair evaluation uses the same frozen repository, tasks, permissions, checks, and reviewers for every agent.
Bottom line
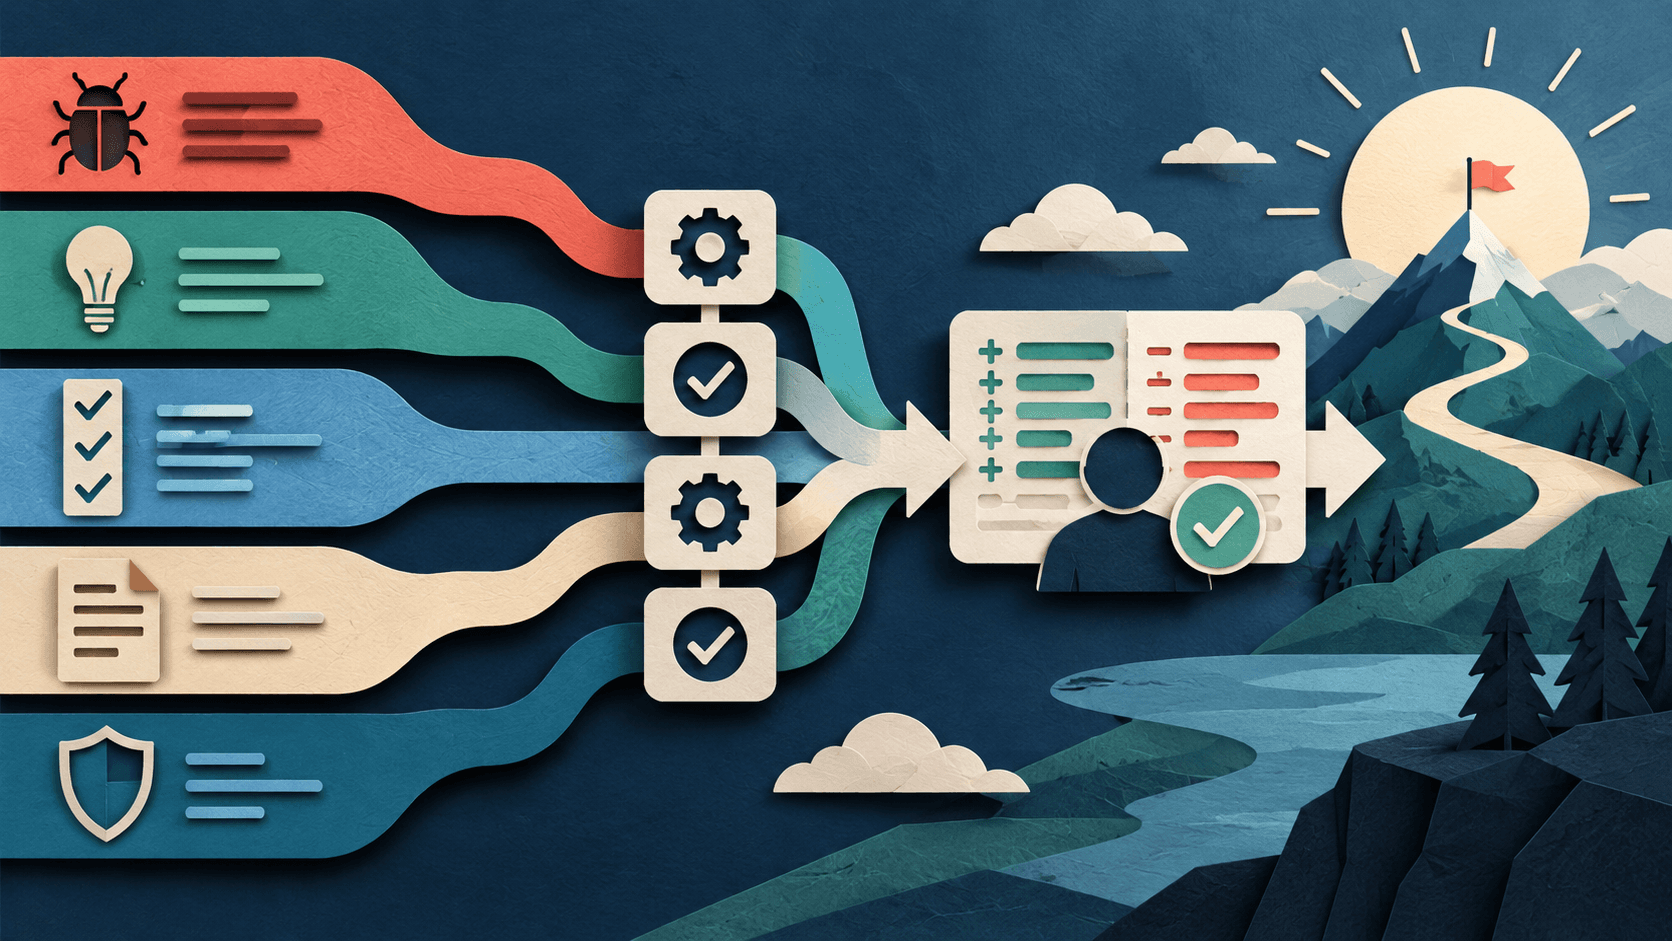
Evaluate an AI coding agent on five real task classes: a bounded bug fix, small feature, missing tests, behavior-linked documentation, and a security review with planted false positives. Use clean snapshots and identical permissions. Score completion, checks, accepted-diff percentage, correction time, cost, unauthorized changes, and severe regressions.
Editorial accountability
Who checked this guide
- Evaluation type
- Research-based verification
- Last materially checked
- Evidence
- 4 listed sources
Hands-on testing is identified explicitly. Research-based coverage uses cited product documentation and other named sources; it does not imply every paid plan was used. Read the full methodology.
Editorial basis
What this guidance is based on
- Editorial basis
- Source-led analysis
- Primary references
- 4
- Products covered
- 3
- Last checked
- 2026-09-26
Important limits
- • Features, prices, limits, and model availability can change.
- • Vendor claims are not independent proof of outcomes.
In this guide
Short answer
Evaluate an AI coding agent on five real task classes: a bounded bug fix, small feature, missing tests, behavior-linked documentation, and a security review with planted false positives. Use clean snapshots and identical permissions. Score completion, checks, accepted-diff percentage, correction time, cost, unauthorized changes, and severe regressions.
Free AI governance buyer checklist
Know what the tool can read, write, retain, and trigger.
Get a checklist for access, evidence, security, ownership, and rollback—plus one decision-ready briefing a week.
Prepare
Use a disposable representative repository with setup instructions, tests, linting, types, and seeded issues. Remove production credentials and customer data. Freeze one baseline commit. Document paths, commands, network, dependencies, and approval actions.
Five tasks
Choose one reproducible bug; one bounded feature; one meaningful test task; one documentation task matching behavior; and one security review with confirmed flaws plus tempting non-issues. Keep difficulty useful but finishable.
Scorecard
Record completion, tests, accepted lines divided by proposed lines, corrections, review minutes, unnecessary files, dependencies, unauthorized actions, errors, severe regressions, versions, tokens or credits, and cost. Report medians and every severe event.
Review
Require a plan, diff, test evidence, and explanation. Blind the reviewer where practical. Apply the same rubric and stop conditions. Reset between runs. Repeat tasks and distinguish agent failure from environment failure.
Decision
Adopt only if accepted throughput improves without exceeding severe-error, permission, and review thresholds. Begin with low-risk repositories and read-heavy tasks. Re-evaluate after major model, price, policy, or workflow changes.
Sources and verification
Product details and claims were checked against the following primary sources.
Frequently asked questions
How many tasks should a pilot include?
Start with at least five task classes and repeat representative tasks enough to expose variability.
What is accepted-diff percentage?
It is the share of proposed code changes retained after human review and correction.
Should agents use the internet?
Only when required, through an allowlist and with the same policy for every product.
How often should teams re-evaluate?
After material model, product, pricing, security, repository, or policy changes.
Recommended tool
Use Cursor if this workflow fits your team
It has one of the clearest workflow fits in its category and is easier to recommend than tools that only look impressive in demos.
Tools mentioned in this article
Cursor
The AI-first code editor that feels like the future of programming
Cursor is a VS Code fork rebuilt from the ground up around AI. It understands your entire codebase and can make multi-file changes with natural language commands.
Claude
Anthropic's thoughtful, safety-focused AI with exceptional long-form reasoning
Claude excels at deep analysis, long-form writing, and nuanced reasoning. Built by Anthropic with a focus on safety and helpfulness.
GitHub Copilot
The AI pair programmer that lives inside your editor
GitHub Copilot is the most widely adopted AI coding assistant, deeply integrated into VS Code, JetBrains, and GitHub itself.
Read next