TypeSafe AI’s Jev Is Betting That AI Should Make Decisions, Not Write More Text
By trading open-ended generation for typed choices, scores, and probabilities, Jev could make narrow AI decisions cheap enough to embed throughout software.
Bottom line
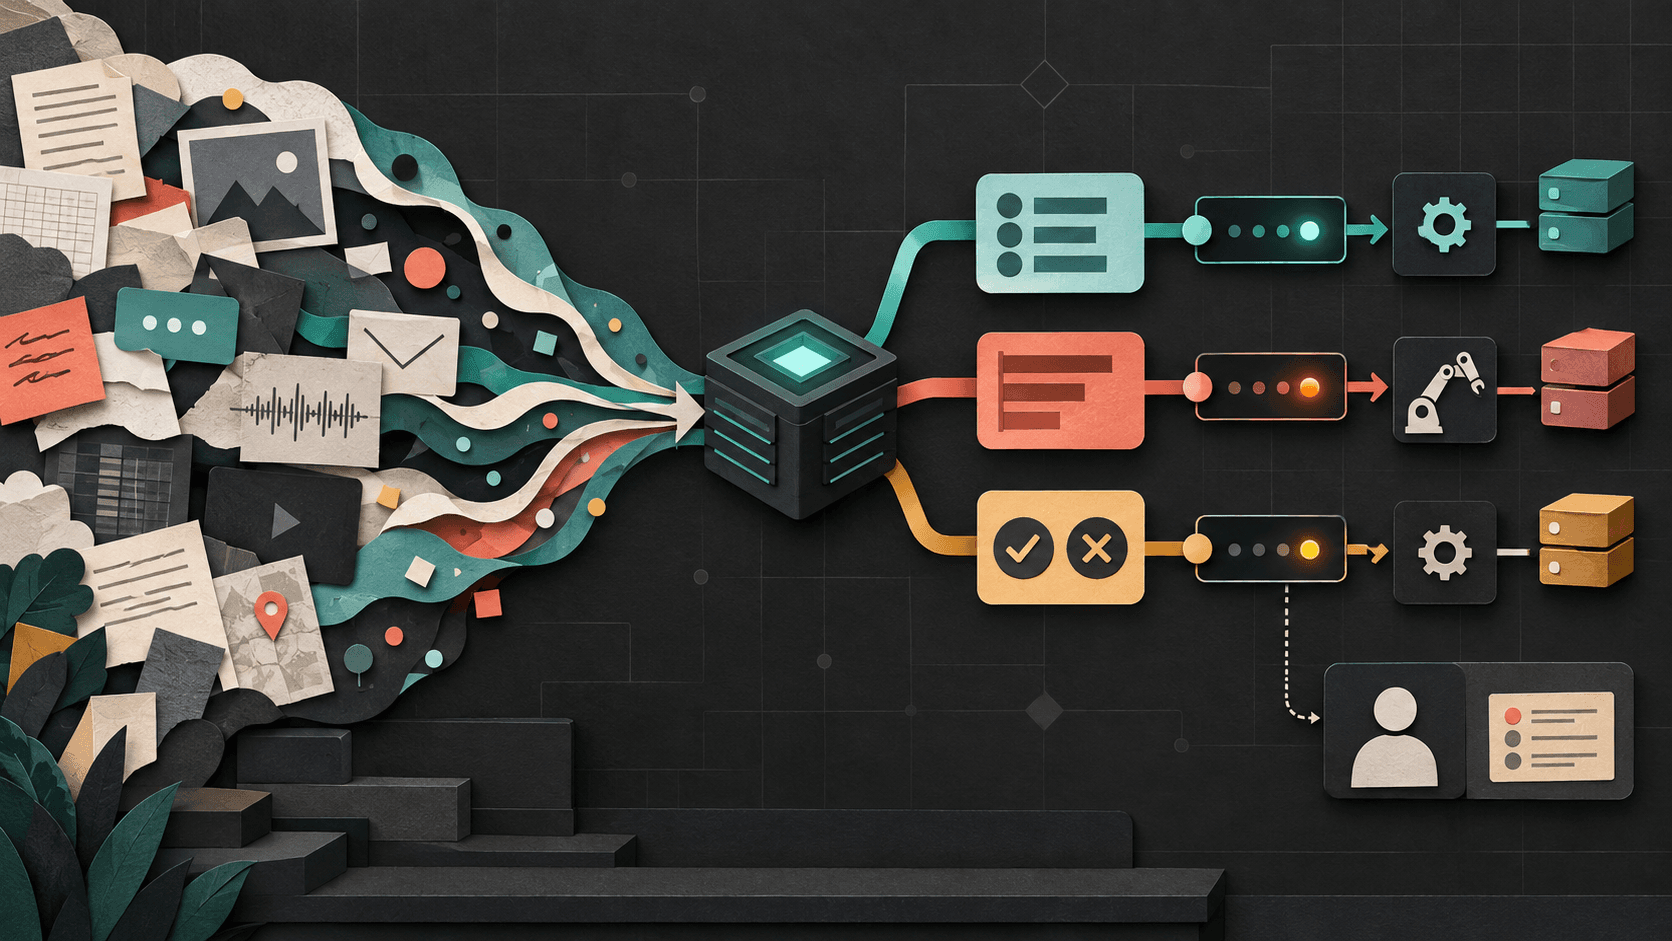
TypeSafe AI is building Jev as a machine-native decision layer rather than another chatbot. Its opportunity is not better prose, but fast, inexpensive judgments that software can validate, route, and escalate.
Editorial accountability
Who checked this guide
- Evaluation type
- Research-based verification
- Last materially checked
- Evidence
- 6 listed sources
Hands-on testing is identified explicitly. Research-based coverage uses cited product documentation and other named sources; it does not imply every paid plan was used. Read the full methodology.
Editorial basis
What this guidance is based on
- Editorial basis
- Source-led analysis
- Primary references
- 6
- Products covered
- 4
- Last checked
- 2026-09-22
Important limits
- • DiscoverAI did not receive production access or independently validate Jev's accuracy, calibration, latency, reliability, or cost sustainability.
- • TypeSafe's workflow evaluations are vendor-run and use frontier-model consensus probabilities rather than independently verified ground truth.
- • Jev remains in early access, and its pricing, availability, limits, SDKs, and behavior can change.
In this guide
Short answer
TypeSafe AI is taking a deliberately different route from the chatbot market. Its first public model, Jev, does not generate open-ended prose. It takes unstructured state, answers predefined questions, and returns typed choices, scores, or yes/no probabilities that software can use directly.
That constraint is the product. Jev is designed to sit inside applications as a fast semantic decision layer: classify this request, score this risk, decide which route fits, or estimate whether a condition is true. If TypeSafe's early claims hold up on real workloads, users gain an opportunity to place AI in high-volume paths where conventional language models can be too slow, expensive, or unpredictable.
Jev is still in early access, and TypeSafe's most prominent workflow results are vendor-run. The opportunity is credible enough to test, not proven enough to assume.
Free AI service workflow checklist
Keep customer-facing AI helpful and supervised.
Get a checklist for escalation, consent, accuracy, permissions, and recovery—plus one practical briefing a week.
What TypeSafe AI is doing differently
Most large language models are trained to produce strings for people. Even when developers request JSON, the underlying product is still generating tokens sequentially, then relying on a schema, parser, validation, and retries to make the answer safe for code.
TypeSafe starts with the software interface instead. Jev receives shared state and atomic questions expressed through three primitives:
- Choice selects from a fixed set of named options.
- Score rates an item against ordered, descriptive levels.
- Noul returns the probability that a statement is true.
The output space is defined in advance. TypeSafe says Jev evaluates outputs in parallel, returns probabilities with every answer, and adds confidence for Choice and Score. It calls this model category “System One,” borrowing the idea of fast, intuitive judgment rather than slow, open-ended reasoning.
This is more than structured-output formatting. The company says it built a new architecture, parallel sampler, and training method—Reinforcement Learning for Calibrated Decisions—around the narrower job. Jev gives up writing, explanation, and arbitrary schemas in exchange for a decision interface intended to behave more like a software primitive.
The opportunity: intelligence inside ordinary code
Jev's most important possibility is what TypeSafe calls a “smart if-statement.” Many products contain decisions that are too contextual for hard-coded rules but too small to justify a slow agent: Which queue should receive this ticket? Does this invoice need review? Is this retrieved passage relevant? Does an agent's proposed action satisfy policy?
Today, teams often handle those cases with brittle keywords, a general-purpose model wrapped in prompts and parsers, or people reading every item. A low-cost decision model could make a fourth pattern practical:
- Pass the relevant state to Jev.
- Ask a small set of explicit questions.
- Let ordinary code combine the returned probabilities.
- Act only when the confidence and business-risk thresholds allow it.
- Escalate uncertain or consequential cases to a person or a larger model.
The software remains in control of permissions, side effects, and policy. The model supplies bounded judgment rather than running the whole workflow.
Where users could create value
Route and prioritize at high volume
Support teams could classify intent, urgency, customer risk, and required expertise in one request, then route only high-confidence cases automatically. Sales and operations teams could apply the same pattern to lead qualification, document intake, claims triage, or moderation queues.
Add an inexpensive verification layer
Agent builders could use Jev to score proposed tool calls, check whether retrieved evidence supports an answer, detect likely policy violations, or decide when an output needs a second look. This does not make the underlying agent correct, but it can create a fast circuit breaker before an action reaches production.
Make real-time experiences more adaptive
TypeSafe publishes a 70–500ms response range for Jev. If a buyer reproduces that performance, it could support interactive decisions in product interfaces, games, recommendations, and live workflow guidance where multi-second model calls feel sluggish. TypeSafe's Doom and Wikipedia-racing demonstrations illustrate this thesis, but demos are not substitutes for application-specific tests.
Process datasets that were previously uneconomic
TypeSafe lists Jev at $0.042 per million input tokens ($42 per billion) and does not meter output tokens. The economic opportunity is not merely replacing one expensive call. It is evaluating many more records, questions, or checkpoints than a team could justify with conventional model pricing—provided the resulting decisions are accurate enough to matter.
Why confidence matters more than a label
A category alone tells software what Jev selected. A probability and confidence estimate help software decide what to do with the selection.
That distinction enables selective automation. A team might auto-route low-risk tickets above a validated confidence threshold, send ambiguous tickets to a person, and prohibit autonomous action entirely for high-impact categories. Thresholds can also vary by consequence: a recommendation widget can tolerate more uncertainty than a payment, security, employment, or healthcare decision.
TypeSafe says confidence is calibrated, meaning higher-confidence groups should be correct more often. Buyers must verify that relationship on their own labeled data. Calibration can change across domains, languages, input quality, and time.
Type-safe does not mean factually correct
TypeSafe's “zero hallucinations” language needs a careful reading. Because Jev chooses within predefined types rather than generating arbitrary strings, it can avoid malformed or invented output fields. That is valuable. It can still choose the wrong option, assign the wrong score, or produce a misleading probability.
In other words, type safety removes one failure mode; it does not guarantee decision accuracy. Teams still need representative evaluation data, risk-based thresholds, monitoring, fallbacks, and human review.
The company's published workflow evaluations also require context. TypeSafe reports results as high as 193.6 times faster and 444.6 times cheaper, while explicitly describing those figures as likely near the high end. The reference answers are averages from frontier models rather than independently verified ground truth, and the workflows were created by TypeSafe's model-capabilities team. The public queries and disagreements improve transparency, but they do not establish performance on a buyer's process.
Who should explore Jev first
The strongest early candidates are product and automation teams with:
- a large volume of repeated, bounded decisions;
- clear allowed answers that fit Choice, Score, or Noul;
- historical examples or outcomes for evaluation;
- meaningful latency or API-cost pressure;
- a safe path for abstention, escalation, and rollback.
Jev is a weaker fit when the desired output is a report, explanation, email, code, creative asset, or complex custom object. It is also a poor place to hide deterministic business logic. Arithmetic, permissions, contractual rules, and irreversible side effects should remain in conventional code.
A practical opportunity test
Pick one decision that happens often and already has a measurable outcome. Ticket routing, retrieval filtering, invoice escalation, and agent-output review are sensible starting points.
Build a labeled holdout set that reflects real edge cases. Run Jev, the current rule system, and a conventional model through the same examples. Measure decision accuracy, calibration, latency, cost, abstention, reviewer time, and the business cost of each error type. Set thresholds on the holdout set, then shadow live traffic without triggering side effects.
Expand only if Jev improves the full workflow, not merely the API bill. A cheap incorrect decision can be much more expensive downstream.
The larger bet behind TypeSafe AI
TypeSafe's thesis is that the next useful AI interface may not look like a conversation at all. It may look like a small, probabilistic function called thousands of times inside ordinary software.
That is what makes Jev unusual. It is not competing to be the model that does everything. It is trying to become the model developers trust for a specific class of fast, closed-set judgment. The narrower interface could limit adoption, or it could be exactly what lets teams move AI from a visible assistant into dependable infrastructure.
For a deeper assessment of maturity, pricing, privacy, alternatives, and production controls, read our [full TypeSafe AI Jev review](/articles/typesafe-ai-jev-review-2026).
This is a research-based news analysis of TypeSafe's September 2026 launch materials and current documentation. DiscoverAI has not received production access or independently validated Jev's speed, accuracy, calibration, reliability, or economics.
Sources and verification
Product details and claims were checked against the following primary sources.
Frequently asked questions
What makes TypeSafe AI's Jev different from an LLM?
Jev is built to return predefined choices, scores, and yes/no probabilities for software rather than generating open-ended text. TypeSafe says its architecture, sampling, and training are optimized around fast, calibrated decisions.
What can users build with Jev?
Likely use cases include routing, classification, scoring, retrieval filtering, agent-output verification, moderation, and other repeated closed-set decisions where software can act above a validated threshold and escalate uncertain cases.
Does type-safe output mean Jev is always correct?
No. A type-safe response fits the allowed structure, but Jev can still select the wrong choice, score, or probability. Users need labeled evaluations, calibrated thresholds, monitoring, and escalation.
How much does TypeSafe AI Jev cost?
TypeSafe currently lists $0.042 per million input tokens, or $42 per billion, with no metered output-token charge. Jev is in early access, so access, limits, and commercial terms can change.
Recommended tool
Use TypeSafe AI if this workflow fits your team
Jev's decision-native interface is a meaningful alternative to forcing a text generator through JSON schemas, parsers, retries, and confidence prompts.
Tools mentioned in this article
TypeSafe AI
Typed, confidence-aware AI decisions for software workflows
TypeSafe AI's Jev model turns unstructured state into typed choices, scores, and yes/no probabilities for automation code.
Google Gemini
Google's deeply integrated AI assistant with unmatched access to Google's ecosystem
Gemini combines powerful AI with Google's vast data ecosystem — Search, Gmail, Docs, YouTube, and more — for a uniquely integrated experience.
Read next
