Atria Dawn Preview Releases Open Agent Weights: What Its Benchmark Claims Mean
Shanghai AI Laboratory's preview targets research and engineering workflows that end in checkable artifacts, but its scale, self-reported evaluations, and sparse operating details narrow the practical audience.
Bottom line
Atria Dawn Preview pairs MIT-licensed weights with an agent-training pipeline built around verifiable outcomes. Its benchmark lead is promising, not independent proof.
Editorial accountability
Who checked this guide
- Evaluation type
- Research-based verification
- Last materially checked
- Evidence
- 4 listed sources
Hands-on testing is identified explicitly. Research-based coverage uses cited product documentation and other named sources; it does not imply every paid plan was used. Read the full methodology.
Editorial basis
What this guidance is based on
- Editorial basis
- Source-led analysis
- Primary references
- 4
- Products covered
- 0
- Last checked
- 2026-09-16
Important limits
- • Features, availability, and pricing can change after publication; confirm consequential details with the provider.
In this guide
*This research-based analysis covers Atria Dawn Preview materials available on September 16, 2026. DiscoverAI has not run the weights or reproduced the evaluations. Parameter counts, benchmark results, and productivity findings are reported by the Atria team unless stated otherwise.*
The short answer
Shanghai Artificial Intelligence Laboratory released Atria Dawn Preview, an open-weight agentic model built on the 744-billion-parameter mixture-of-experts GLM-5.2 foundation. The BF16 and FP8 checkpoints are published under the MIT License, with a 256K context window plus hosted and local deployment paths.
The release is aimed at long research and engineering tasks: gathering evidence, writing and running code, conducting experiments, recovering from failures, and producing an inspectable artifact rather than stopping at plausible prose. The accompanying paper reports the highest result among its comparison set on five of 16 benchmarks. Those are provider-reported results, not independent replications, and the preview's real value will depend on hardware, scaffolding, tool permissions, reproducibility, and total task cost.
What is Atria Dawn Preview?
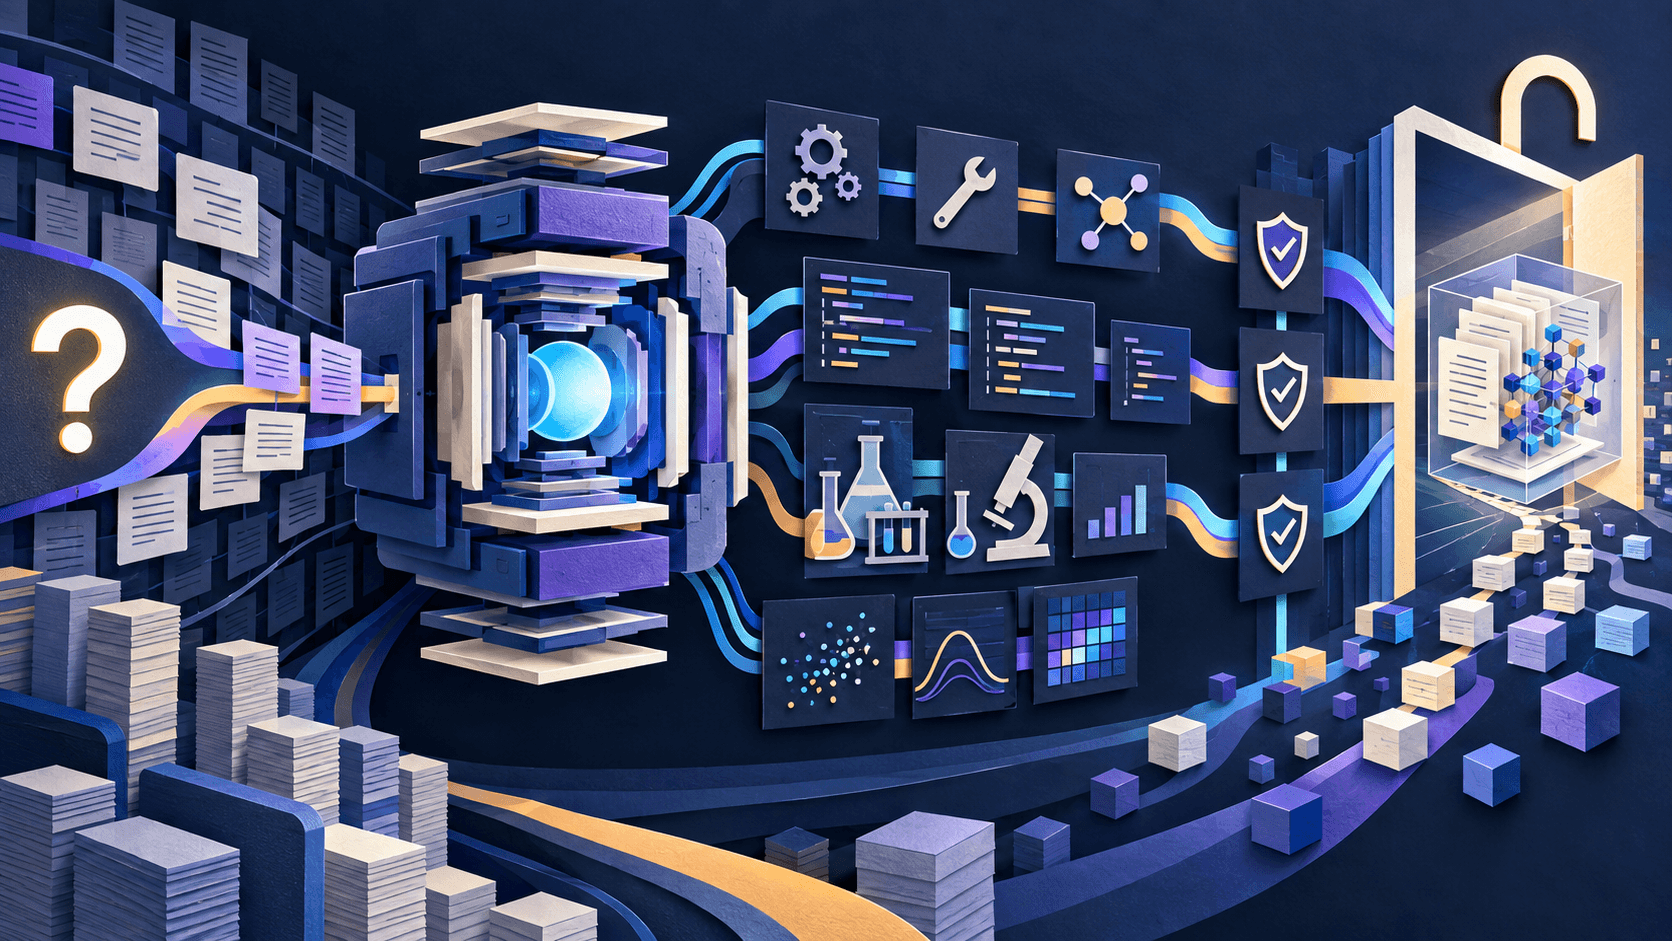
Atria is a text-input, text-output agentic model rather than a consumer chatbot product. The project describes four broad task families: discovery, creation, delivery, and authorized cybersecurity work. Its central training idea is a Verifiable Experience Pipeline that connects model actions to executable environments or externally checked outcomes.
That is a useful direction. Agent transcripts can look persuasive while producing a broken program, irreproducible analysis, fabricated citation, or missing file. Training and evaluating against artifacts and environment feedback moves attention toward whether work actually completes. It does not eliminate specification errors: an agent can faithfully optimize the wrong metric or produce a reproducible but invalid experiment.
Are Atria Dawn's benchmark results credible?
The team reports evaluations across 16 research, engineering, cybersecurity, browsing, coding, and digital-work benchmarks, with Atria leading the listed systems on five. Its repository, for example, reports 92.5 on BrowseComp, 86.5 on CyberGym, and 96.0 on DeepSearchQA under the project's evaluation setup.
Treat the table as a release claim, not a league table carved in stone. Agent benchmarks are sensitive to prompts, tool environments, retry budgets, model versions, graders, and whether competitors were tested under equivalent scaffolding. Small score differences can be noise, and a broad benchmark win does not predict reliability on a company's private repositories, laboratory protocols, or office workflows.
A credible internal test should freeze the harness, disclose tool and token budgets, run repeated trials, score task artifacts blindly, and include failure cases. Compare accepted output per dollar and reviewer hour—not only pass rate.
What does open weight mean here?
The repository publishes instruct and FP8 checkpoints through Hugging Face and ModelScope and places code and model weights under the MIT License. That gives capable teams more deployment and modification freedom than an API-only release. It does not mean the full training data, training system, or all infrastructure is reproduced by downloading a checkpoint.
Scale is the immediate constraint. A 744B-parameter foundation is far beyond ordinary workstation deployment, even with lower-precision weights. Teams need substantial accelerator memory, distributed serving expertise, inference security, observability, and a plan for patches. FP8 reduces the footprint but does not turn the model into a laptop download.
There is also a number worth preserving rather than smoothing over: the project describes the GLM-5.2 foundation as 744B parameters, while Hugging Face currently displays 753B parameters for the released checkpoint. The reviewed materials do not reconcile those figures, so teams sizing infrastructure should inspect the actual weight files instead of treating either rounded label as a memory estimate.
The project also offers hosted access for international and China regions. Public materials reviewed for this article do not publish a durable hosted price, service-level agreement, training-data cutoff, or enterprise data-processing terms. Buyers should request those in writing before sending proprietary code or research data.
What did the human collaboration study find?
The paper analyzes 769 task records from 56 participants who used the model during development. The authors report that roughly one-third of completed AI-assisted tasks were judged infeasible without the agent. This is interesting qualitative evidence about where an agent may expand a researcher's reach.
It is not a randomized productivity trial. Participants worked in the model's development context, the sample was small, and “infeasible” was a participant judgment. The study can generate hypotheses about useful workflows; it cannot establish that a typical organization will complete one-third more work or receive a particular return on investment.
Who should evaluate Atria Dawn Preview?
The clearest candidates are research institutions, infrastructure teams, and engineering organizations with the hardware and expertise to evaluate a very large open-weight agent—or teams willing to test the hosted preview on non-sensitive work. Smaller organizations are likely to get a faster answer from a managed frontier API unless model control or a particular Atria capability justifies the operational burden.
Run a bounded bake-off: choose 20 representative tasks with known acceptance criteria; isolate credentials and network access; log every tool action; repeat runs; and have domain experts grade the final artifacts without knowing the model. Include impossible tasks, poisoned documents, ambiguous requests, and recovery from failed tools. Stop if the agent cannot make uncertainty visible or if reviewer time erases the claimed gain.
The verdict
Atria Dawn Preview is noteworthy less for a fractional benchmark lead than for combining permissively licensed weights with an explicit focus on verifiable, end-to-end agent work. It gives well-resourced teams another inspectable foundation for research automation and provides useful ideas for evaluating whether agents deliver artifacts instead of theater.
The preview label matters. Independent benchmark replications, transparent hosted pricing, operational documentation, and production evidence are still limited. Open weights improve control and auditability, but they transfer deployment, security, and reliability work to the operator. Atria should enter a disciplined evaluation queue—not a production environment on the strength of its release table alone.
Sources and verification
Product details and claims were checked against the following primary sources.
Frequently asked questions
What is Atria Dawn Preview?
Atria Dawn Preview is a text-based agentic model from Shanghai Artificial Intelligence Laboratory, built on the 744B-parameter GLM-5.2 foundation for research, engineering, tool use, and artifact-producing workflows.
Is Atria Dawn open source?
The project publishes BF16 and FP8 model weights and code under the MIT License. Open weights do not by themselves reproduce the training data, training pipeline, or production infrastructure.
What context window does Atria Dawn Preview support?
The official repository lists a 256K-token context window for both the instruct and FP8 checkpoints.
Does Atria Dawn beat GPT and Claude models?
The Atria team reports the highest score in its comparison set on five of 16 benchmarks. These are provider-reported evaluations and should be independently reproduced under equal tool, prompt, and compute budgets before guiding deployment.
Found this useful?
Get the next one in your inbox.
One five-minute briefing a week: a meaningful change, a practical workflow, and a clearer tool decision—already filtered for lean teams.
Free · one email a week · unsubscribe any time
Read next
Recommended for you
AI Implementation for Small Business: Launch Your First Workflow in 30 Days
A delivery-focused companion to AI readiness: take one approved use case from baseline to a monitored production decision.
A four-week implementation playbook for turning a qualified small-business AI use case into a controlled, measured workflow.
Read guide
How to Automate Business Tasks With Zapier and AI in 2026
Claude vs. ChatGPT for Small Business in 2026: Which Should You Pay For?
Fish Audio Review 2026: Is Its AI Voice Cloning Worth It?