Google’s Federated AI Update: Verify the Privacy Boundary
Google’s October 2 research shifts training into protected server workloads. We explain encrypted uploads, auditability, and the limits of the privacy claim.
Bottom line
Google’s October 2 research shifts training into protected server workloads. We explain encrypted uploads, auditability, and the limits of the privacy claim.
Editorial accountability
Who checked this guide
- Evaluation type
- Research-based verification
- Last materially checked
- Evidence
- 3 listed sources
Hands-on testing is identified explicitly. Research-based coverage uses cited product documentation and other named sources; it does not imply every paid plan was used. Read the full methodology.
Editorial basis
What this guidance is based on
- Editorial basis
- Source-led analysis
- Primary references
- 3
- Products covered
- 0
- Last checked
- 2026-10-07
Important limits
- • DiscoverAI has not performed a hands-on product test or independently reproduced vendor results.
- • Features, prices, availability, and policies can change; verify the applicable plan and configuration.
In this guide
Short answer
Google’s new federated-learning system changes where sensitive computation happens while trying to make its privacy rules externally checkable. The useful lesson is to ask for evidence of the processing boundary rather than assume that a federated label means data never leaves a device.
What Google announced
The October 2 research post describes protected server execution, authorized workloads, and public transparency logs. Google says Gboard has adopted the system. Its headline should not be read as proof that every AI service now offers this architecture.
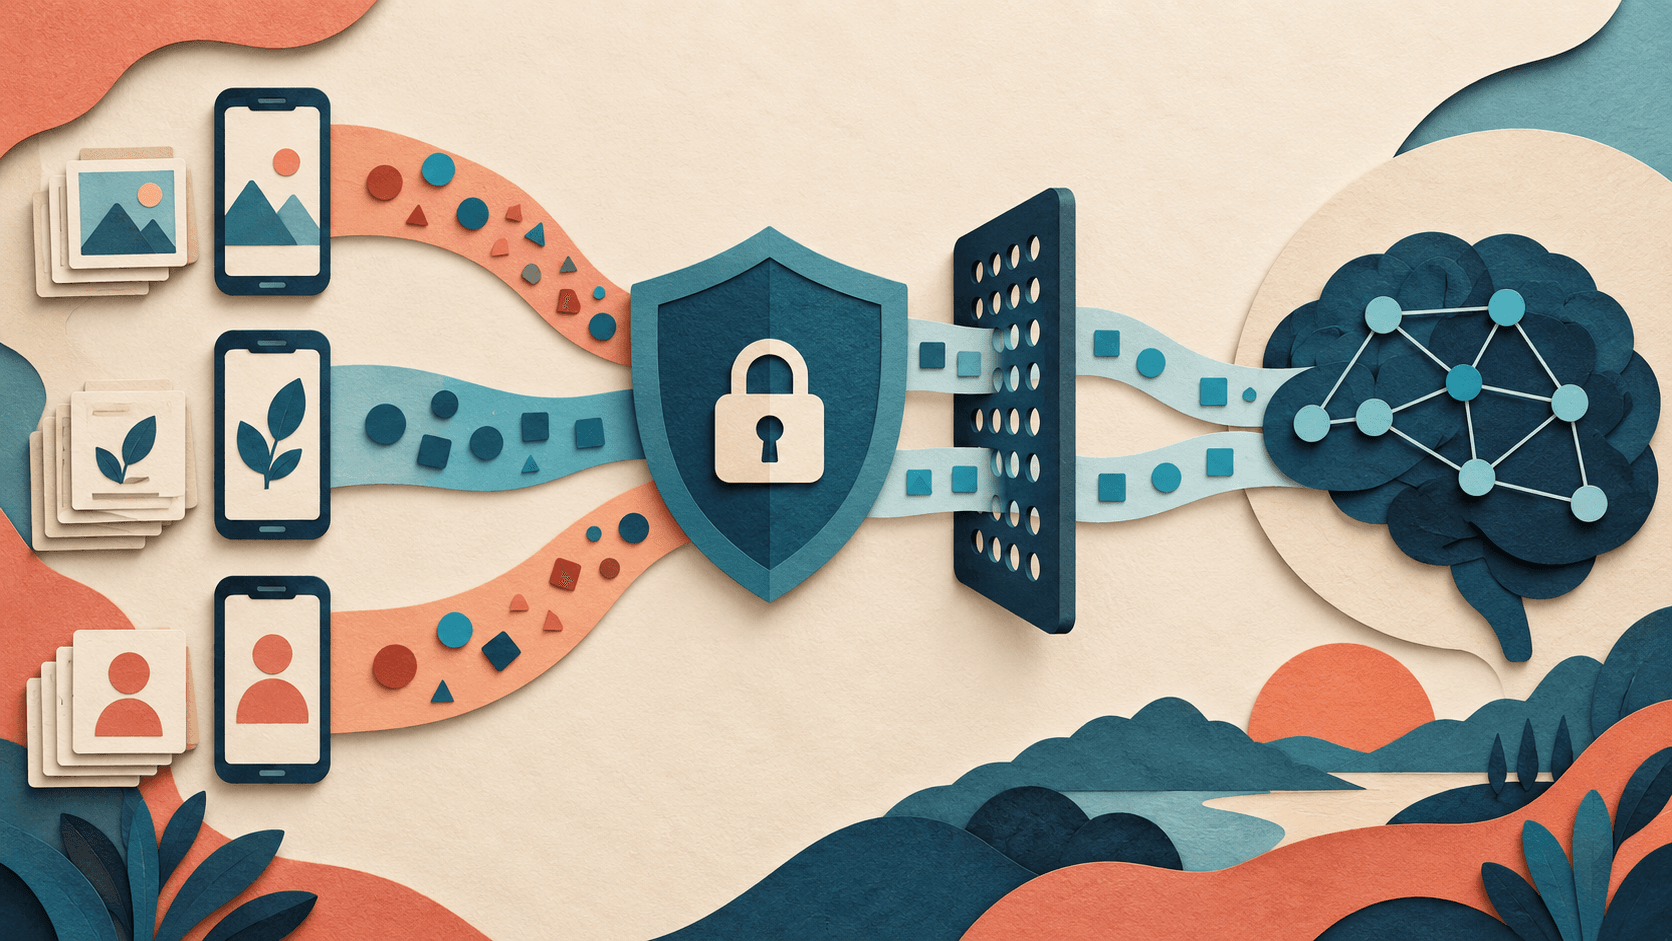
The accompanying preprint explains that devices upload encrypted data tied to policies limiting which programs may process it. Server-side trusted execution environments perform the authorized work. The authors report improved training and privacy-utility tradeoffs compared with their earlier system. The paper is an arXiv preprint; DiscoverAI has not independently validated those results.
Federated does not mean device-only
This design matters because it complicates a familiar shortcut: describing privacy solely through the location of the original records. Here, encrypted examples leave devices, while the processing and release rules constrain how they can be used. Buyers need to distinguish encryption in transit, permitted computation, released outputs, and retention.
For a small organization, the practical question is whether a supplier can explain those boundaries in a way the responsible technical owner can inspect. A marketing phrase does not tell you who can decrypt content, which workloads are approved, or what happens when a component changes.
Auditability is an operational requirement
Google publishes Confidential Federated Compute code, providing an inspection path for technical teams. Open code is useful evidence, but the presence of a repository does not certify your deployment or prove that an unrelated product runs the same software.
Our editorial recommendation is to ask vendors for a concrete account of verification: what is logged, what can be checked independently, who checks it, and how a failed check affects processing. Also ask whether the published policy covers every route by which sensitive information might be used.
What the claim does not settle
The research discusses hardware and side-channel limitations and leaves broader correctness proofs as future work. A mathematically described privacy mechanism should not be translated into an unconditional promise that no information can ever leak.
The architecture also does not answer whether your organization should collect a particular record in the first place. Minimize the material needed for the task before assessing how a vendor processes it. If a process can work with public or synthetic examples, use those for the initial evaluation.
Questions for an AI supplier
Ask for a diagram naming where records, keys, updates, and released results live. Ask which programs may access sensitive inputs and how changes to those programs are authorized. Ask who can inspect the execution evidence, how long encrypted inputs remain available, and which failures suspend the workflow.
These are proposed procurement questions, not a certification checklist or legal advice. A qualified technical reviewer should interpret the evidence for the actual use case. Keep a written distinction between vendor statements, materials inspected, and controls verified in your environment.
What to do now
Most small teams do not need to build a federated-training platform. They can use this announcement to demand clearer explanations of processing and verification from existing suppliers. Read our [agent-privacy analysis](/articles/google-agentic-privacy-contextual-security-report-2026) for the related question of who may act on information once a system has access to it.
Sources and verification
Product details and claims were checked against the following primary sources.
Frequently asked questions
Does data stay on the phone?
Not in this design: devices upload encrypted training data for authorized processing in server-side protected environments.
Is this a universal privacy guarantee?
No. The system has stated assumptions and limitations; it does not certify other products.
Has Google deployed it?
Google reports adoption in Gboard. DiscoverAI has not independently audited that deployment.
Should a small team build this?
Usually the immediate benefit is better supplier questions, rather than building training infrastructure.
Read next