DiscoverAI Answer-Engine Visibility Benchmark: Methodology
A transparent protocol for future results; no scores are published until collection and verification are complete.
Bottom line
This is the public protocol for DiscoverAI's recurring answer-engine visibility benchmark. It defines the prompt set, controls, scoring, verification, and release threshold before results exist. It does not claim a winning platform or current market score. Publishing the method first prevents metrics from being redesigned around an attractive result.
Editorial accountability
Who checked this guide
- Evaluation type
- Research-based verification
- Last materially checked
- Evidence
- 4 listed sources
Hands-on testing is identified explicitly. Research-based coverage uses cited product documentation and other named sources; it does not imply every paid plan was used. Read the full methodology.
Editorial basis
What this guidance is based on
- Editorial basis
- Source-led analysis
- Primary references
- 4
- Products covered
- 2
- Last checked
- 2026-09-26
Important limits
- • Features, prices, limits, and model availability can change.
- • Vendor claims are not independent proof of outcomes.
Short answer
This is the public protocol for DiscoverAI's recurring answer-engine visibility benchmark. It defines the prompt set, controls, scoring, verification, and release threshold before results exist. It does not claim a winning platform or current market score. Publishing the method first prevents metrics from being redesigned around an attractive result.
Free content AI buyer checklist
Choose tools that improve accepted work—not output volume.
Get a checklist for accuracy, edit time, sourcing, brand fit, and cost per accepted asset—plus one briefing a week.
Research question
For fixed commercial AI-tool questions, which brands and sources are mentioned or cited, how accurately are they represented, and how stable are observations across ChatGPT, Gemini, Claude, and Google AI results? The study measures outputs, not secret ranking factors.
Sample
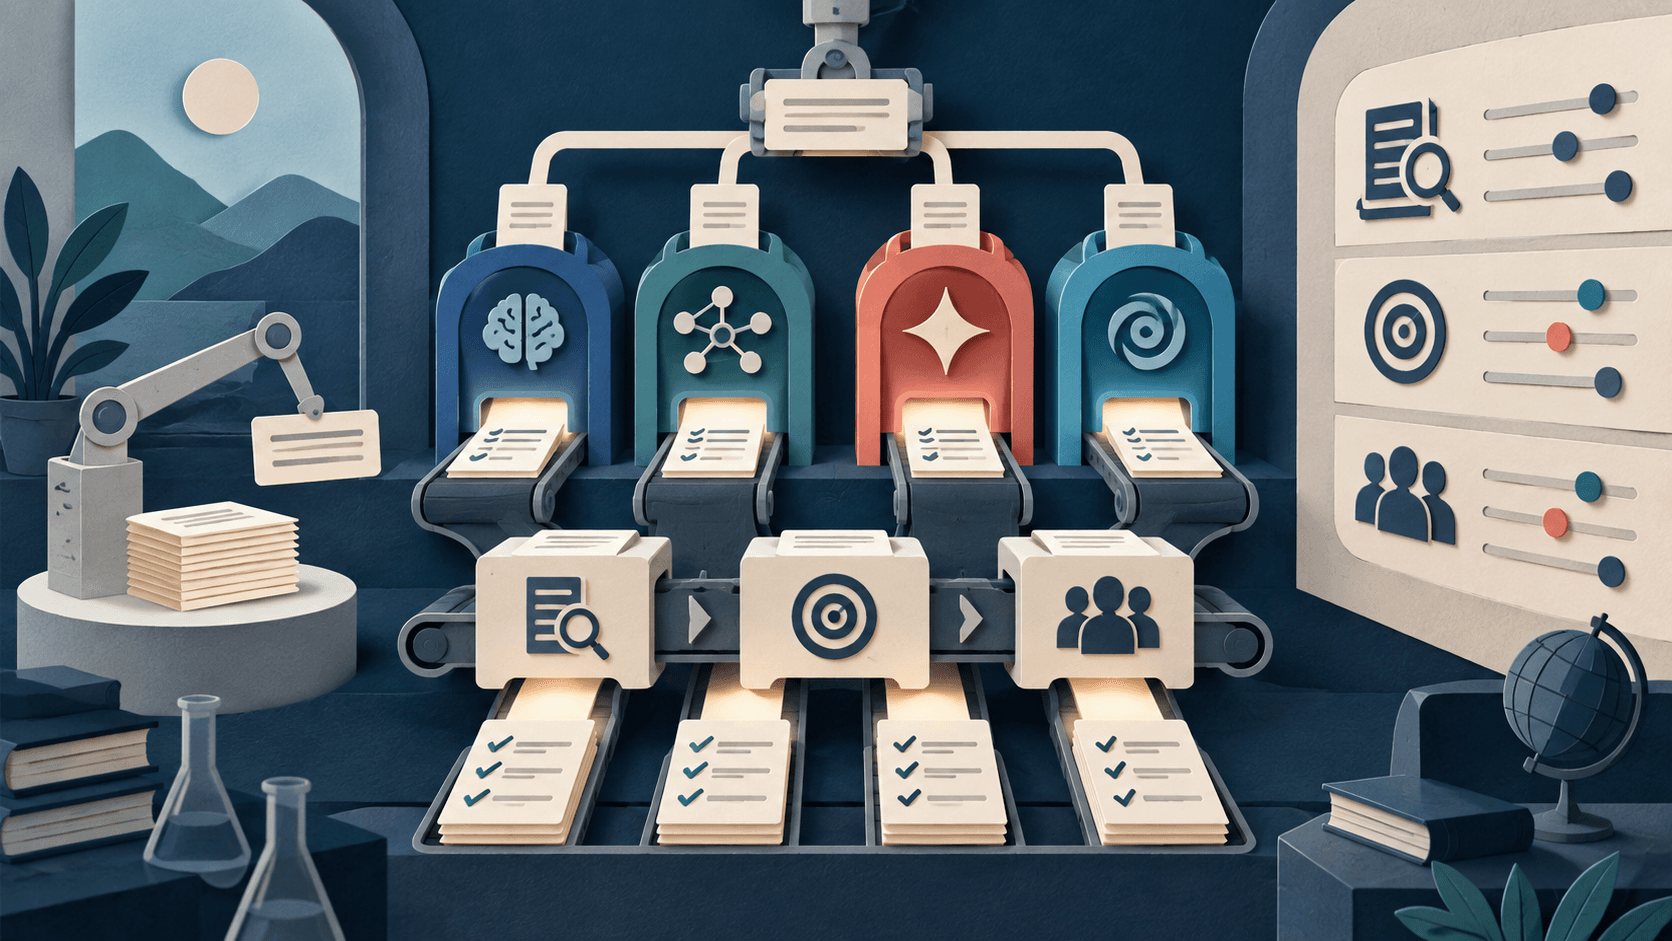
Use 25 versioned prompts across five intents and run each three times per engine in a declared country and language. Use fresh sessions, record account and retrieval state, and collect in a narrow window. Archive responses, citations, timestamps, model labels, and failures.
Scoring
Score eligible brand mention, owned-domain citation, ordered position, predefined factual claims, and volatility separately. Two reviewers adjudicate ambiguity. A composite is optional and must publish weights; raw components remain primary.
Quality and conflicts
Freeze prompts and scoring before collection. Reviewers disclose commercial relationships. Affiliate status never changes scoring. Vendors may correct objective entity errors but cannot preview comparative results or purchase inclusion. Publish exclusions and corrections.
Release gate
Results ship only after every observation has its raw answer, conditions, citation check, and reviewer status. The dataset will expose prompt ID, intent, engine, run, brand, mention, citation, position, accuracy, volatility, and notes. Until then, this remains methodology—not evidence.
Sources and verification
Product details and claims were checked against the following primary sources.
Frequently asked questions
Does this page contain results?
No. It publishes the method and labels results as pending collection and review.
Why publish methodology first?
It reduces temptation to change prompts, metrics, or weights after seeing results.
Will affiliate relationships affect scores?
No. Commercial relationships stay outside eligibility, scoring, and adjudication.
Can this reveal ranking factors?
No. It measures observed answers under stated conditions, not hidden mechanics or causation.
Recommended tool
Use Profound if this workflow fits your team
Profound is a serious shortlist for established brands building a measurable answer-engine optimization program. It connects prompt demand, brand visibility, citations, crawler behavior, AI-referred traffic, and content workflows. Its biggest limitation is attribution: observed mentions, citations, and visits do not by themselves prove incremental revenue or that a Profound recommendation caused a change.
Tools mentioned in this article
Profound
Profound is a serious shortlist for established brands building a measurable answer-engine optimization program
Profound is a serious shortlist for established brands building a measurable answer-engine optimization program. It connects prompt demand, brand visibility, citations, crawler behavior, AI-referred traffic, and content workflows. Its biggest limitation is attribution: observed mentions, citations, and visits do not by themselves prove incremental revenue or that a Profound recommendation caused a change.
OmniSEO
Track brand mentions, citations, prompts, and competitors across AI search
OmniSEO is an AI-search visibility platform for researching prompts, monitoring brand mentions and citations, benchmarking competitors, and prioritizing AEO and GEO work.
Read next